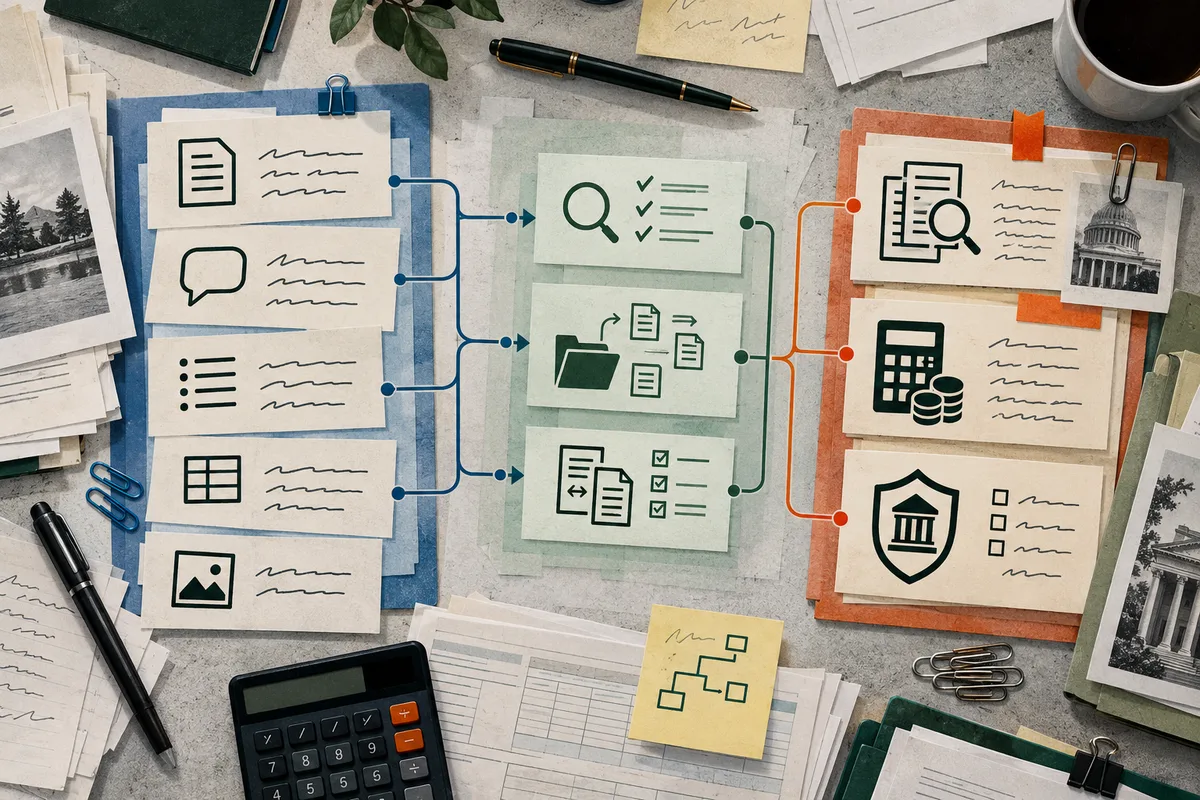
Use AI for a grant-writing task only when the input is permitted, the output can be checked against an authoritative source, and the right reviewer is available. O*NET maps grant writing within the broad Fundraisers occupation, but does not measure an individual writer’s task mix or AI exposure. Verify claims against records, reconcile budget assumptions through the responsible finance process, and follow instructions that apply to the specific opportunity. If permission, evidence, or qualified review is missing, work manually or practice with synthetic material.
How can a grant writer use AI without confusing assistance with evidence?
A U.S. grant writer can use AI for a bounded transformation when the input is permitted, the output can be checked against authoritative material, and a person with relevant knowledge is available to review it. That can include reorganizing approved text or proposing clearer wording. It does not make an unsupported claim true, establish a budget basis, or decide whether a cost or promise is allowed. Funders, employers, contracts, and tool settings may impose different rules, so check the rules for the particular application and system before entering material. If the source, permission, or reviewer is missing, keep that task manual until the gap is resolved.
Apply that test to the specific step, not to an application as a whole. Reformatting a public funder instruction into a working outline may be checkable against the instruction itself; deciding whether the organization qualifies, whether a result is representative, or whether a cost belongs in the request needs the governing facts and appropriate authority. A polished passage can still omit a condition or overstate what a source says. Review should therefore compare meaning, not just grammar: confirm that the transformation preserves scope, qualifications, dates, figures, and unresolved questions. If that comparison cannot be made efficiently, the task is not yet a good candidate for AI assistance.
What work is actually inside a U.S. grant writer’s role?
“Grant writer” can sound like one writing job, but an application is a chain of distinct tasks. A writer may locate opportunities, interpret instructions, assemble organizational and program facts, shape a case for support, draft narrative sections, coordinate a budget, check attachments and limits, obtain approvals, and submit through a funder’s system. Some assignments cover only prose; others include research, project coordination, or stewardship after an award. The title alone therefore cannot tell a worker which parts of their week are changing or where assistance might fit.
The official O*NET OnLine profile, “13-1131.00 - Fundraisers,” lists Contract Grant Writer as a sample title within the broader Fundraisers occupation and includes grant-related duties. That is useful evidence that grant writing sits inside a wider occupational category. It is not a time-use study of grant writers: the profile does not say what share of an individual’s work is searching, drafting, budgeting, coordinating, or checking. Nor does an occupational task description measure which tasks a particular employer has adopted AI for. Use it as a vocabulary for mapping work, not as a personal exposure score.
The U.S. Bureau of Labor Statistics’ “Fundraisers | Occupational Outlook Handbook” projects 6% employment growth for Fundraisers from 2025 to 2035 and about 10,000 openings per year over the decade. BLS notes that many openings are expected as workers transfer to other occupations or leave the labor force. These are dated demand signals for the broad Fundraisers occupation, which includes but does not isolate grant writers; they do not identify grant-writer-specific demand, explain the projected growth, attribute it to AI, or predict an individual outcome. Read with O*NET, this evidence describes an aggregate work category, while the decision here concerns a person’s tasks and workplace.
A practical map starts with recent applications and recurring work, rather than a generic job description. For each task, note its input, output, frequency, consequence of error, and who owns the underlying facts or approval. Opportunity research may end in a shortlist, but eligibility and strategic fit depend on organizational priorities and funder terms. Instruction tracking may produce a compliance checklist, but someone still has to identify the controlling notice and interpret ambiguous requirements. Drafting turns program records into a narrative; it does not create the results, commitments, or community needs those records should substantiate.
Budget coordination is another task bundle: gathering estimates, checking units and effort, aligning figures with narrative, and routing questions to finance or grants staff. Arithmetic can be checked mechanically, while the assumptions and authorization behind an amount remain organizational decisions. Review and submission add their own work: matching claims to records, confirming attachments and versions, resolving open questions, securing sign-off, and entering or uploading material in the required system. These steps can be distributed among several people, so the same title may conceal very different responsibility and review arrangements.
Turn the map into a personal inventory by marking which outputs are repeatable transformations of known material, which depend on current authoritative instructions, and which require judgment or delegated authority. Record who can verify each output and where the source lives. This distinguishes a drafting task that might be checked from a decision that belongs to a program owner, finance lead, or authorized signer. It also reveals whether an apparent writing bottleneck is actually missing records, unclear ownership, or late approvals. Those differences matter more for a safe workflow choice than the occupational label by itself.
This task map is a starting point, not a finding that grant writing will disappear or remain unchanged. A capability to produce text does not show that a funder or employer has adopted it, that the surrounding coordination work has vanished, or that demand for proposal work has risen or fallen. The O*NET classification and BLS outlook cannot answer those individual questions. They support a narrower conclusion: the title covers varied work, so assess exposure and possible assistance at the task level, then verify each proposed use against the records, rules, and people responsible for that application.
Sources: 13-1131.00 - Fundraisers | O*NET OnLine; Fundraisers | Occupational Outlook Handbook | U.S. Bureau of Labor Statistics
Which writing tasks can AI assist with while keeping the source authoritative?
AI can help reshape material that already has an authorized source: turn approved notes into an outline, reformat a verified passage for a different field, offer a plain-language alternative, or flag inconsistent names and dates across drafts. These are proposals for transformations, not new facts. The writer should be able to point from every retained statement to the record, instruction, or accountable person that supports it. If a requested sentence needs a fact that is absent from the source, the useful output is a question or a marked gap, not plausible prose that fills it.
For this workflow, an authoritative source is the record designated by the organization or governing application process as controlling for that particular fact or requirement. It may be a current approved program record, a signed-off budget estimate, a funder instruction applicable to the opportunity, or a named owner’s confirmation. The label is contextual: a spreadsheet may control the approved amount but not establish participant outcomes; a public webpage may explain a general process but not supersede an active notice. Before drafting, identify what source is authoritative for the field in question, who can resolve conflicts, and whether the source is current. AI cannot choose that authority merely because one document is longer, newer-looking, or written more confidently.
A practical handoff keeps a small provenance trail beside the proposed text: source title or record location, relevant date or version, owner, and status such as approved, draft, or awaiting confirmation. Include the specific passage, table, or field when possible. Keep the generated wording distinct from the source itself, and retain an open question wherever source materials disagree. This makes review faster because a program lead can inspect the underlying fact rather than infer where a sentence came from. It also makes revision safer: when the source changes, the writer can identify dependent language instead of treating a previously fluent paragraph as settled truth.
Consider a hypothetical application whose approved program notes state that workshops are planned, but do not yet report attendance or outcomes. A writer might ask a tool to organize those notes under a funder’s narrative headings or produce a shorter version for a character limit. The draft should preserve the status “planned” and point back to the approved notes. If the tool changes planned workshops into workshops already delivered, or adds a number of participants, the output has crossed from transformation into unsupported generation. The correction is not to find a more persuasive prompt; it is to restore the source’s status and leave the missing result unclaimed until an accountable owner supplies it.
The same boundary applies to citations and commitments. A tool may help format a citation already selected by the writer, but a plausible reference is not proof that a study exists or supports the sentence. It may suggest concise language for an approved commitment, but it cannot enlarge the organization’s promise of staff time, services, matching funds, or future results. Keep proposals visibly provisional until the relevant source owner approves them. Where the record supports only a narrower statement, prefer that statement even if it sounds less complete. The grant narrative should reflect what the organization can substantiate and authorize, rather than what would make the paragraph read smoothly.
Consistency flags are useful when treated as leads. A tool can compare two supplied drafts and point out that a project name, period, or figure differs; it cannot determine which version is correct without the controlling record. Ask it to report both versions and where they appear, then have the owner resolve the discrepancy. Likewise, an outline can expose a missing section, but a blank heading does not authorize invented content. Define the task narrowly, supply only permitted material, request explicit markers for gaps and uncertain transformations, and review the result against the source. Fluency, completeness, and confident phrasing are properties of the output; none establishes evidence or approval.
A bounded task is therefore one whose transformation can be inspected without asking the model to supply missing premises. Keep the source attached, preserve qualifications and status, and route factual conflict or proposed commitments to the person with authority. If a passage cannot be traced, label it as a question or remove it. This gives AI room to reduce repetitive drafting work while leaving evidential ownership where it belongs: with records and accountable people.
How can evidence and citations be checked efficiently?
The efficient check is claim by claim: separate each sentence into statements that could be independently true or false, locate the original material behind each one, and compare the exact wording with what that material establishes. A citation attached to a paragraph is not enough if it supports only one clause. Mark the outcome as supported, narrower than drafted, inference, unresolved, or unsupported. Then revise, qualify, remove, or route the claim. This turns review from a vague request to “fact-check the draft” into a finite set of decisions and prevents a sound citation from lending borrowed authority to neighboring claims it does not establish.
Start by splitting compound sentences. “The program served local families, improved school attendance, and reduced food insecurity” contains distinct claims about who was served and two outcomes. One source may document attendance while another describes the program design; neither should be assumed to establish all three. Make one row per testable proposition, or annotate the sentence so each clause has its own source. If the clauses depend on different populations, periods, or measures, keep those boundaries visible in the prose. A shorter sentence is often easier to verify and less likely to convert a limited observation into a broad statement about the whole program.
Open the cited source itself and inspect the relevant passage, table, methods, and definitions rather than relying on a search snippet or a citation generated by a tool. Check whether it concerns the same population and setting as the application, covers the period the sentence names, and uses the geography being claimed. Inspect the denominator and measure: a count of people enrolled is not automatically a count completing a service, and a self-reported change is not automatically an independently measured outcome. Note whether the evidence is a direct record, a published study, an administrative dataset, or an interpretation. These source types answer different questions; the draft should not imply a stronger design or broader coverage than the material provides.
Next, test the wording against the result actually reported. Does the source establish an association or a causal effect? Does it describe an average, a subgroup, a single site, or a defined sample? Is the period current enough for the statement, and does the source describe the population the proposed grant will serve? A source can be genuine and still be a poor fit. When it supports only a narrower proposition, narrow the prose rather than stretching the source. When a citation is secondary, follow it to the underlying record or study if available; if that cannot be checked, disclose the limitation in the draft or avoid making the consequential claim.
Use a hypothetical needs statement: “In 2025, 40% of county students missed at least ten school days, showing that our tutoring program will raise attendance.” Before retaining it, split the sentence. The first clause requires a source that defines county students, the school year, the absence threshold, and the denominator behind 40%. The second makes a causal prediction about the proposed program; a local absence statistic alone cannot establish that effect. A verified district report might support a carefully scoped description of absenteeism, while the prediction would need separate evidence and a defensible connection to the intervention. If such support is absent, state the documented need and describe the program’s intended contribution as a plan, not a proven result. This example is invented for illustration, not a reported local finding.
Label the remaining reasoning honestly. If a writer connects two verified facts to explain why a service may fit a need, that connection can be an inference; say what it rests on and do not attribute it to a source that did not make the argument. Keep forecasts, targets, prior outcomes, and aspirations distinct. A target approved by the organization is evidence of an intended goal, not evidence that the goal has already been achieved. If a figure is preliminary, identify its status and owner or leave it out until confirmed. For citations, check that author or issuing body, title, date, location, and link identify the source actually opened, then verify that the cited passage is relevant to this claim rather than merely on the same subject.
A compact claim ledger can make the work manageable: claim text, source and exact location, population and period, reported measure, limitation, and decision. Sort first by consequence: claims about eligibility, need, outcomes, budget rationale, and organizational capacity deserve prompt resolution because an error could alter the application’s meaning. Routine descriptive wording can follow once the consequential claims are secure. Record unresolved questions with an owner and due point instead of allowing a polished draft to conceal them. The ledger is a navigation aid, not a substitute for reading the underlying evidence or obtaining the right organizational judgment.
Finally, distinguish traceability from adequacy. A complete citation trail proves where a statement came from; it does not make an old source current, a narrow sample representative, or a weaker source suitable for the claim. Look for the strongest relevant evidence available and preserve its limits. If evidence conflicts, describe the disagreement or choose the source most applicable to the stated population and explain the choice. If evidence is missing, remove the claim, narrow it to what is documented, or state it as an uncertainty requiring confirmation. The check is complete only when the language, source, scope, and level of certainty match.
Why can a correct total still be an incorrect grant budget?
A correct total answers only an arithmetic question: do the entered figures add up? A defensible grant budget also needs a supportable cost basis, a match between the figures and proposed work, and a determination that the costs are allowable under the rules governing this application. Those are separate checks. For a covered federal award, “2 CFR Part 200 Subpart E: Cost Principles” sets the relevant cost principles; it does not make every plausible expense allowable or decide a particular line without its facts and award terms. A private funder may use different rules, so identify the applicable terms before treating federal rules as controlling.
Start with the basis for each amount, before checking its sum. A basis is the record or calculation explaining what the line represents and how its amount was derived: a vendor quote, approved pay rate, documented estimate, allocation method, or other appropriate support. Record enough context to reproduce the calculation: unit, quantity, rate, effort, period, assumptions, and source date where relevant. “Travel: $4,000” is a total; it does not explain the number of trips, travelers, fare assumption, or project purpose. “Two staff trips × two people × $1,000 estimated round-trip fare” exposes the inputs for review, although the estimate and proposed travel still need support and approval.
Reconcile the calculation with the narrative and schedule. If the project description promises four workshops but the budget supports two, the sum may be correct while the plan and requested resources disagree. If personnel costs reflect six months of effort but the narrative describes a year-long activity, check whether the schedule, effort, or description is incomplete. Review units as well as totals: hours versus days, monthly versus annual rates, per-participant versus whole-project costs, and partial versus full effort. A spreadsheet can verify multiplication; it cannot tell whether the rate is current, the effort is realistic, the allocation is justified, or the narrative accurately describes what the organization intends to do.
A hypothetical line item shows the distinction. Suppose a proposal lists a coordinator at $30 per hour for 10 hours each week over 12 weeks, totaling $3,600. The arithmetic is consistent: 30 × 10 × 12 = 3,600. But a reviewer still needs to know whether the rate is supported, whether 10 hours a week is a reasonable estimate of the described duties, whether all 12 weeks fall in the project period, and whether the organization has approved that commitment. If the narrative says the coordinator will work 15 hours weekly, the discrepancy needs resolution even though the line total is mathematically correct. This illustration supplies no real wage or grant estimate.
Allowability is a further, rule-based judgment. Under “2 CFR Part 200 Subpart E: Cost Principles,” costs for covered federal awards are evaluated under applicable principles and provisions, including whether they are necessary and reasonable for the award, allocable to it, treated consistently, and not barred by a specific restriction. The exact analysis depends on the cost category, recipient context, award terms, and facts. A line that is customary for an organization is not automatically chargeable to a particular award; a cost that can be calculated and documented may still be prohibited or assigned elsewhere. Conversely, missing documentation in a draft may mean the basis has not yet been assembled, rather than establish that the underlying cost is impermissible. Keep those conclusions distinct.
“2 CFR § 200.302 Financial management” concerns financial systems and records for covered recipients and subrecipients, including identifying federal award sources and uses. That award-management duty helps explain why a budget needs traceable inputs and a record trail, but it is not a universal pre-award narrative format or a substitute for the opportunity’s instructions. For a nonfederal funder, consult its terms and the organization’s applicable policies instead of importing Part 200 by habit. In either setting, a budget narrative should explain material assumptions in a form that lets a reviewer connect amounts to activities and lets the organization later identify what was proposed.
An AI tool can help recalculate a supplied formula, flag inconsistent units, or compare two versions of a line-item table. Treat each as a clerical check: verify the formula and source figures independently, and preserve the original records. The tool cannot establish that a quote is genuine or current, choose the correct pay rate, decide how shared costs should be allocated, determine whether a purchase is allowable, or approve an organizational commitment. Confidence in a generated explanation has no bearing on those questions. If the source documents disagree, mark the variance and ask the responsible owner; do not let an AI-generated reconciliation silently choose one input.
The practical answer is to match documentation to an item’s size, uncertainty, and consequence. A stable unit cost may need a concise source and calculation; a shared salary allocation or unusual purchase may need its method, assumptions, and explicit review. Label estimates as estimates, state their basis, and update them when material assumptions change. Arithmetic establishes consistency among numbers; it does not establish support, program fit, allowability, or approval.
Sources: 2 CFR Part 200 Subpart E: Cost Principles | eCFR; 2 CFR § 200.302 Financial management | eCFR
Which instructions control when a notice, agency guide and template differ?
For a specific U.S. application, determine the controlling instructions from the active funding notice and its amendments, then follow the agency’s guidance that the notice makes applicable, the required forms, and the submission system’s constraints. Apply organizational policies as an additional layer for internal approval, records, and authorized commitments. These sources may govern different things, so a difference is not automatically a conflict. A page describing general practice cannot silently replace an opportunity-specific condition, and an internal checklist cannot waive a funder requirement.
Begin with the actual opportunity identifier and the notice currently in force. Check for amendments, corrected attachments, revised deadlines, or incorporated instructions before drafting against a saved copy. The notice may specify eligibility, required content, page limits, attachments, evaluation criteria, or which agency guide and form package apply. Capture the notice title or number, version or amendment, relevant section, and the date checked. If an amendment changes one requirement, retain the link between the changed text and the affected draft or checklist item so the team does not continue using an earlier version by accident.
Next, follow the notice’s references to applicable agency guidance and forms. “How to Apply – Application Guide” from NIH Grants & Funding illustrates this layered approach for NIH: applicants are directed to the instructions applicable to their funding opportunity alongside the NIH application guide. That guidance is NIH-specific; it is not a universal template for federal or private grants. Likewise, the NSF “Proposal & Award Policies & Procedures Guide (PAPPG)” is published in versions with applicability dates. A writer must check which version governs the submission rather than assume the newest version applies to every proposal or retroactively. Where instructions address different layers—for example, a notice’s project-specific limits and a guide’s general form completion rules—follow each within its stated scope.
Grants.gov’s “Pre-Award Phase” is useful orientation for common steps and emphasizes that processes vary by grant and awarding agency. It can help a writer understand the broad sequence and locate agency material, but it does not settle the requirements of a particular competition. Treat it as a route to the source, not the final authority for page limits, allowable attachments, or submission-specific eligibility. For a foundation or other private funder, use that funder’s current solicitation and terms; do not assume NIH, NSF, or Grants.gov rules govern it merely because the application resembles a federal form.
Forms and portals add operational requirements. A form may impose a character limit or require a field, while the submission system may enforce file type, naming, validation, or authorized-submitter rules. Those mechanics matter, but distinguish them from substantive eligibility or cost judgments. A portal’s acceptance of a file does not prove that its content meets the review criteria. Conversely, a narrative that satisfies the notice may still fail submission if it violates a system constraint. Record both the source of the requirement and the stage at which it applies, so a formatting rule does not get mistaken for policy about the project itself.
Organizational policy adds internal approval paths, data handling, budget sign-off, and delegation limits. It may be stricter than a funder’s minimum, but cannot authorize departure from a binding funder condition. If the two appear inconsistent, preserve the exact language and refer it to an authorized grants, compliance, or institutional official.
When sources appear to disagree, check whether they address the same issue, application type, and effective period. A template may predate an amendment; a general guide may defer to the notice; a portal may enforce a technical limit without changing a substantive requirement. Compare exact passages and dates, then identify whether the notice incorporates a particular version. If applicable instructions still conflict, seek written agency clarification or an authorized organizational interpretation and retain it with the file.
Use a checklist as an index, not as authority. Each row can record the requirement, controlling document and version, section, owner, completion evidence, and status. Link the source and keep unresolved interpretation distinct from routine formatting checks. When instructions change, update the row and identify affected narrative, budget, forms, or approvals.
Sources: Pre-Award Phase | Grants.gov; How to Apply – Application Guide | NIH Grants & Funding; NSF Proposal & Award Policies & Procedures Guide (PAPPG)
What information may enter an AI tool?
Permission is specific to the material, system, configuration, and purpose. Before pasting proposal text, a budget file, reviewer comments, or organizational records into an AI tool, check the employer’s policy, the funder’s or contracting party’s terms, and any confidentiality or data-handling obligation attached to the material. Then check the tool’s applicable terms and the account settings that govern retention, access, reuse, and deletion. A system being described as private or enterprise does not, by that label alone, show that this use is approved. The writer needs a rule or authorization that covers the actual data flow.
Make the decision at the level of the proposed input. Public program descriptions may be usable under rules that prohibit uploading a nonpublic draft; synthetic examples may be acceptable for testing a prompt when live records are not. A file can contain several kinds of information with different handling requirements, so consider whether a passage includes personal information, unpublished research, confidential organizational details, a partner’s data, or sensitive budget assumptions. Remove material that is unnecessary to the task, and avoid including names, identifiers, or full documents when a narrower excerpt would do. Minimization reduces the amount exposed, but it is not itself permission to disclose what remains.
Check the full operating path rather than only the product name. Which account and model will receive the prompt? Are settings controlled by the organization or by an individual user? Who can access inputs and outputs, how long are they retained, can they be used to improve a service, and can an administrator or other authorized party retrieve them? Does the tool connect to plugins, storage, or other services that receive the content? The answers may depend on the plan, configuration, and contract in force. If documentation is unclear, or the organization has not approved the system for this material, pause and ask the person responsible for data governance or procurement. Do not infer an exception from convenience or a reassuring interface label.
The NSF notice, “Notice to Research Community: Use of Generative Artificial Intelligence Technology in the NSF Merit Review Process,” illustrates why the role and direction of a rule matter. NSF encourages proposers to disclose AI use and holds proposers responsible for proposal accuracy and authenticity. Its restriction on uploading proposal contents to non-approved tools addresses reviewers handling confidential submissions. That reviewer prohibition should not be recast as a universal ban on applicants using AI, nor does proposer guidance amount to blanket approval to upload an applicant’s materials. A writer must identify whose conduct the notice governs and still check the applicable organizational and opportunity rules.
Likewise, “2 CFR § 200.303 Internal controls” requires effective controls and reasonable cybersecurity measures for entities within its covered federal-award scope. That requirement makes sound information handling relevant to award administration; it does not name or approve a vendor, settle a particular data transfer, or replace an organization’s own authorization process. The adjacent financial-management requirements have their own scope and do not establish a general AI prompt policy. For a private funder or an entity outside the covered context, identify the contract, solicitation, and organizational rules that actually apply instead of importing a federal regulation by analogy.
When permission is unresolved, choose a task that needs no restricted input: ask for a generic outline using public instructions, test a transformation on synthetic text, or draft manually until an authorized person answers. Record the decision’s scope, such as which account, data category, task, and settings were approved, and revisit it if any of those change. Keep separate the questions “may this information be entered?” and “is the resulting text accurate?” A careful fact check cannot cure unauthorized disclosure, just as permission to process a file does not make the generated statements reliable. Both decisions must be satisfied before using the output in an application.
Sources: Notice to Research Community: Use of Generative Artificial Intelligence Technology in the NSF Merit Review Process | NSF; 2 CFR § 200.303 Internal controls | eCFR
Who should review the output, and what does each reviewer check?
Assign review by the decision being made. The writer can check whether an AI-assisted passage preserves the supplied meaning, follows the requested format, and links each factual statement to the intended source. That check does not make the writer the source of program facts, the approver of a cost, or the interpreter of every funder rule. Name a person who can answer each substantive question, and leave unresolved matters visible instead of smoothing them into declarative prose.
The program or project owner should confirm the underlying activity: who the proposal will serve, what services will occur, when they will occur, which partners are involved, what capacity exists, and which outcomes are plans, targets, prior results, or still unknown. This person should compare the narrative against current program records and explain discrepancies. If AI turns a planned activity into a completed one, expands a target into a claimed result, or adds a commitment the team has not made, the program owner must resolve the factual status. The writer can edit the correction into clear language but should not decide that the more polished version is true.
The record owner or subject-matter source should verify facts tied to evidence they maintain: for example, a research lead for study details, a data steward for a dataset definition, or the person responsible for an organizational statistic. Ask them to confirm the specific claim and the source version, population, period, and measure, rather than requesting a broad endorsement of the draft. Where a source is preliminary or another record conflicts with it, record the limitation and ask who can resolve it. A citation can be formatted by the writer, but source authority comes from the underlying record and its custodian, not from fluent wording or a generated reference.
Finance or the grants-management function should review the budget basis and the connection between costs, activities, periods, and approved organizational assumptions. A spreadsheet or AI calculation can flag arithmetic or inconsistent units, while the competent finance reviewer checks the source rate, effort, allocation method, estimate, and applicable treatment. For a covered federal award, allowability is determined under the relevant rules and facts; the writer’s ability to describe a cost does not supply that judgment. If the organization combines finance and grants work in one role, identify which capacity that person is exercising and what remains outside their authority.
A grants, compliance, legal, or institutional official with delegated responsibility should interpret ambiguous requirements, confidentiality obligations, or apparent conflicts among funder terms and organizational policy. Route the exact question and governing text to that person; do not present an AI summary as an official interpretation. Some questions have a clear document answer, while others require a decision from an authorized official or written clarification from a funder. Preserve the distinction between routine form completion and an unresolved interpretation that could affect eligibility, disclosure, budget treatment, or submission obligations.
The authorized signer or organizational representative must review the final representations and commitments that the organization is asked to certify. Depending on the organization, this may include assurances about accuracy, eligibility, institutional support, matching funds, resources, certifications, or willingness to perform. A writer may prepare and route those statements, but must not imply approval merely because a draft passed editorial review or a portal permits submission. Confirm that the signer has the required authority, has access to the material basis for the representation, and is reviewing the final version rather than an earlier draft.
These functions can sit with fewer people in a small nonprofit or research office; the control is not a particular org chart. It is that consequential questions reach someone competent to answer them and authorized to make the decision. A compact handoff record can list the claim or issue, accountable owner, reviewer, status, source or governing document, open question, and resolution needed by date. For example, mark a participant-count statement “pending program owner confirmation” rather than leaving it to appear final. Use statuses such as supported, revise, unresolved, or approved only when the assigned person has actually made that determination.
Close the loop by returning decisions to the draft and checking the final assembled version. The writer can incorporate approved facts, preserve qualifications, and verify links; the owner should confirm that the revision did not alter the decision they approved. Keep the record proportionate to the risk: a low-consequence wording edit may need a brief comment, while a material outcome claim, cost, disclosure, or certification may call for a traceable approval. If a required reviewer is unavailable or authority is unclear, keep the passage marked as open and do not convert silence into consent. This division lets AI assist with production while people retain the decisions that depend on records, expertise, and delegated authority.
What does the grant-writing pilot actually establish?
The SAGES pilot shows that fluent proposal prose can still receive materially different substantive judgments, but it does not test whether AI helps a grant writer produce a stronger application. In “Assessing ChatGPT’s potential as an autonomous grant writing tool: a pilot study,” researchers asked a GPT-4-based version of ChatGPT, accessed in January 2024, to prepare a surgical grant proposal under instructions from the Society of American Gastrointestinal and Endoscopic Surgeons (SAGES). The relevant result is therefore about one autonomous, generated proposal judged in a particular setting, not a general comparison of human and AI writing or a measurement of workplace productivity.
The prompt supplied an author concept, while the proposal’s applicant, project team, institution and data were fictional. The system generated the proposal without post-generation human edits. This design isolates a narrow question: what happens when the model is asked to create a complete proposal from the supplied concept and directions, then reviewers assess that artifact? It does not represent the more bounded workflow in which a staff writer works from an organization’s actual records, asks the program lead to confirm activities, checks sources, reconciles the budget with finance, and edits a draft before submission. Those steps change both the material available and who is responsible for evaluating it.
Two blinded reviewers assessed the proposal. Both considered it well written, yet their overall ratings diverged: one judged it Good and the other Unacceptable. The study describes reservations involving feasibility, the qualifications of the team, and the research environment. The contrast matters because presentation quality and substantive readiness are separable dimensions. A proposal can read smoothly while leaving reviewers unconvinced that the work can be carried out, that the team has the needed expertise, or that the setting supports the plan. Reviewers’ concerns in this pilot were not an objective audit showing which claims were true or false; they were judgments about the generated application under the study’s review conditions.
The split ratings also limit any simple verdict about quality. With two reviewers, a single proposal and a single review context, the result demonstrates disagreement in this case; it cannot estimate how often reviewers would disagree, establish a typical score, or show that model-written proposals usually succeed or fail. The fictional inputs prevent the pilot from testing whether the system can faithfully represent an actual institution’s capacity, distinguish planned activities from documented results, or build an accurate budget from records. Because the proposal was not edited after generation, the study likewise cannot tell whether a grant writer’s source checking and revision would resolve particular concerns or introduce others.
To answer a practical assistance question, a study would need to compare workflows on comparable proposal tasks: for example, unaided human drafting with a clearly specified, human-assisted AI workflow, using the same authorized source material, instructions and review criteria. It would need enough proposals and reviewers to examine consistency, and it should record time spent drafting and checking, corrections made, unsupported or altered claims, budget and compliance errors, and reviewer assessments. A useful design would state who supplies facts, who edits, how reviewers are blinded where possible, and whether the measured outcome is writing time, factual reliability, proposal quality, or something else. These are proposed comparison features, not findings of the SAGES pilot.
The study’s boundary is consequently important for a writer deciding how much to infer. It gives a concrete example of polished language coexisting with concerns about feasibility, qualifications and environment. It does not establish that bounded human-assisted use is ineffective, that editing would necessarily improve the result, or that AI changes grant writers’ employment. The practical lesson within this section is narrower: do not use fluency as a proxy for substantive assessment. Whether assistance is useful in a particular workflow remains a separate question that depends on the task, source material, checking effort and responsible reviewers.
The authors’ assessment therefore concerns the generated artifact and the reviewers’ evaluation, not whether each concern arose from model limitations, sparse fictional inputs, the proposal concept, or the review process. The pilot cannot separate those possible causes. Nor does “well written” mean that every requirement was met; it records a judgment about prose, while the overall ratings reflect broader assessments. Keeping these dimensions distinct prevents both an overly positive reading based on style and an overly negative reading that treats this particular autonomous result as a test of every assisted drafting method.
Sources: Assessing ChatGPT’s potential as an autonomous grant writing tool: a pilot study
How should a grant writer choose the next capability to strengthen?
Choose a learning investment by tracing a recurring bottleneck to the capability or condition that could actually change it. If the trouble is repeatedly losing time to version comparison, an improved checklist or document workflow may be more useful than a broad AI course. If an approved tool is available but the writer cannot reliably ask it to transform material without changing meaning, a short, task-specific practice sequence may fit. If the recurring gap is deciding whether a claim is supported, building evidence and data literacy is more durable than memorizing one interface. The choice should follow the work problem, not the visibility of a new tool or credential.
Start with recurrence and consequence. List a few recent applications and mark where time, rework, uncertainty or handoff delays accumulated: finding current instructions, locating source records, converting approved text into a required format, checking a budget narrative, or obtaining a decision from an authorized colleague. A one-off inconvenience may call for a small note or template. A repeated failure that could produce a materially misleading claim, unsupported cost, missed requirement or late submission deserves a more deliberate process change and review. This is a diagnostic exercise for the reader’s own workflow, not a claim that one bottleneck is common to all grant writers.
Then ask what is within the writer’s authority. Some problems are skill gaps: the writer may need more practice comparing source versions, checking a claim against its underlying record, or spotting when a calculation’s assumptions do not match the narrative. Other problems are missing conditions: no access to current records, no delegated authority to approve a commitment, unclear rules for tool use, or no available reviewer with the necessary subject or finance knowledge. Training can improve how a person frames a question and documents an unresolved item; it cannot create permission, supply missing evidence, assign organizational authority, or make a colleague available. Escalating a process or access need may be the more relevant next move.
Where capability is the bottleneck, separate durable foundations from interface knowledge. Evidence literacy includes finding the primary record, checking its date and scope, distinguishing an observed result from a plan, and matching the wording of a claim to what the record supports. Data literacy includes understanding definitions, denominators, periods and units well enough to notice when a number has shifted meaning. Workflow judgment includes deciding which transformation is low consequence, what must be checked, when a question needs an owner, and when to stop. These capabilities transfer across tools because they concern the work and the evidence, rather than where a particular button sits.
Tool learning has a place when tied to a permitted, repeatable task: handling a narrow transformation, providing only necessary context, or comparing output with supplied text. Interfaces and settings change, so practice in defining the task, preserving meaning and checking results may last longer than familiarity with a menu. Before paying, confirm the system is approved, practice matches the account available at work, and the training uses material the learner may share. Otherwise, practice with public or synthetic text and seek organizational guidance separately.
Before enrolling or spending, name the practice artifact and feedback source. Workflow learning might produce a requirement register with notice version, owner and completion evidence; evidence practice, a claim-to-source table; budget practice, a reconciliation linking units, rate, period, basis and reviewer; tool practice, a tracked before-and-after transformation with meaning checks. These artifacts let a qualified colleague comment on the work itself. They do not show that a course improves hiring prospects or funding success.
Feedback matters as much as content. A self-paced module may explain a concept without showing whether the learner can apply it. Look for a small practice task and review from someone qualified, or an opportunity to observe how an experienced colleague resolves the issue. Keep restricted proposal material out unless policy and system approval cover the use. If supervised access is unavailable, a public solicitation and invented sample facts can support practice, while actual decisions remain with the responsible owner.
Let time, cost and life constraints set the investment’s size. With a deadline, caregiving duties, health limits or little discretionary income, a brief practice block may fit better than an expensive, long credential. Protected development time may make structured instruction and a project feasible. A degree or career change requires a separate assessment of prerequisites, time, foregone income, location and family responsibilities. Seeing AI used in one task does not by itself justify a major commitment, and no credential guarantees employment or salary.
An adjacent move may fit when valued work shifts toward proposal coordination, evidence and reporting, research administration or document-process improvement. Treat these as options to investigate, not promised openings: compare actual duties, experience requirements, local availability, reliable compensation information and training demands. A larger change may make sense if the desired work differs substantially or the current role cannot meet key constraints. Identify a target task bundle, check entry requirements and test a small project before committing to costly training.
Record the bottleneck, whether it is a skill, process, authority or access issue, the smallest useful practice or organizational change, and who can give feedback. Set a time and spending limit, then review the artifact and errors after one or two tasks. If the problem persists because records or approval are unavailable, address that condition instead of adding courses. If practice closes a checkable skill gap, choose the next step based on what remains. This preserves useful experience while grounding learning decisions in the actual workflow, without implying an employment or income outcome.
What is one proportionate next step?
Before the next live application, test one low-consequence task in a bounded trial: for example, ask an approved tool to turn a public funder instruction into a checklist, or to reorganize synthetic sample text. Keep the source beside the output. Ask the person who owns the requirement or program facts to review the result, and record what they corrected, how long checking took, and whether the task was easier without losing meaning or omitting a condition. Set a stopping rule first: if the output changes a requirement, invents a fact, or takes longer to verify than doing the task manually, stop using it for that task and revise the process. If permission to use the system or a qualified reviewer is missing, do the work manually while resolving that gap; a local trial is not a controlled study or a forecast of career effects.
Keep only the record needed to explain the trial and its decisions. “2 CFR § 200.334 Retention requirements for records” sets retention requirements and triggers for covered federal-award records; it does not create a universal duty to retain every AI prompt or log for every draft. Follow the applicable award and organizational rules. If you want to examine broader task-level change signals, the free checker can help frame that review, but its signals are not a validated probability of displacement. The paid career roadmap can compare paths against your constraints; it does not guarantee income or employment.
Sources: 2 CFR § 200.334 Retention requirements for records | eCFR
Questions readers ask
Can AI determine whether a grant budget is allowable?
AI can help flag arithmetic or consistency questions in permitted material, but a correct sum does not establish that a cost is allowable. Check the amounts against their documented basis and route unresolved cost judgments to authorized finance staff under the applicable award rules.
Which instructions should a grant writer follow?
Identify the active funding opportunity, amendments, and applicable agency instructions, including the versions that govern that submission. Grants.gov offers general orientation; NIH and NSF guidance applies within its stated scope. A generated checklist can help organize requirements but does not decide which rule controls.
Sources and notes
- 13-1131.00 - Fundraisers | O*NET OnLine
O*NET includes Contract Grant Writer as a sample title and grant-related duties among Fundraisers tasks. It maps the occupation broadly, not an individual writer's task shares or AI exposure.
- Fundraisers | Occupational Outlook Handbook | U.S. Bureau of Labor Statistics
BLS projects change for the broad Fundraisers occupation; it does not isolate grant writers, establish an AI cause, or predict an individual outcome.
- Assessing ChatGPT’s potential as an autonomous grant writing tool: a pilot study
One unedited autonomous proposal was generated using January 2024 GPT-4-based ChatGPT, SAGES guidance and fictional applicant/team/data; two blinded reviewers both called it well written but rated it Good and Unacceptable overall. One surgical proposal, one committee and two reviewers cannot establish award success or ordinary assisted workflow effects.
- Notice to Research Community: Use of Generative Artificial Intelligence Technology in the NSF Merit Review Process | NSF
NSF encourages proposers to disclose AI use and holds them responsible for accuracy and authenticity. The non-approved-tool prohibition applies to reviewers handling proposal content, not as a universal applicant ban.
- 2 CFR Part 200 Subpart E: Cost Principles | eCFR
For covered federal awards, Subpart E supplies cost principles; allowability depends on applicable provisions and facts. It cannot validate a specific line or govern every private funder.
- 2 CFR § 200.302 Financial management | eCFR
Covered recipients and subrecipients must maintain financial systems and records identifying federal-fund sources and uses. This is award-management context, not a universal pre-award narrative template.
- 2 CFR § 200.303 Internal controls | eCFR
Covered entities must maintain effective internal controls and reasonable cybersecurity measures. This does not approve a vendor or authorize proposal-data disclosure.
- Pre-Award Phase | Grants.gov
Grants.gov describes common pre-award steps, notes grant-specific variation and directs applicants toward awarding-agency guidance. It is orientation, not controlling instructions for every opportunity.
- How to Apply – Application Guide | NIH Grants & Funding
NIH points applicants to applicable opportunity instructions and NIH application guidance, demonstrating layered NIH-specific instructions rather than a universal rule.
- NSF Proposal & Award Policies & Procedures Guide (PAPPG)
NSF publishes PAPPG versions with effective-date applicability; identify the version governing a specific submission rather than assuming newest guidance applies retrospectively or across funders.
- 2 CFR § 200.334 Retention requirements for records | eCFR
Covered federal-award records have specified retention periods and triggers. This is not a blanket duty to retain AI prompts or logs for every draft.
Apply this to your own work
See the whole job market at once.
Explore which occupations AI may reshape, then turn the signal into a practical response.
Explore the job map