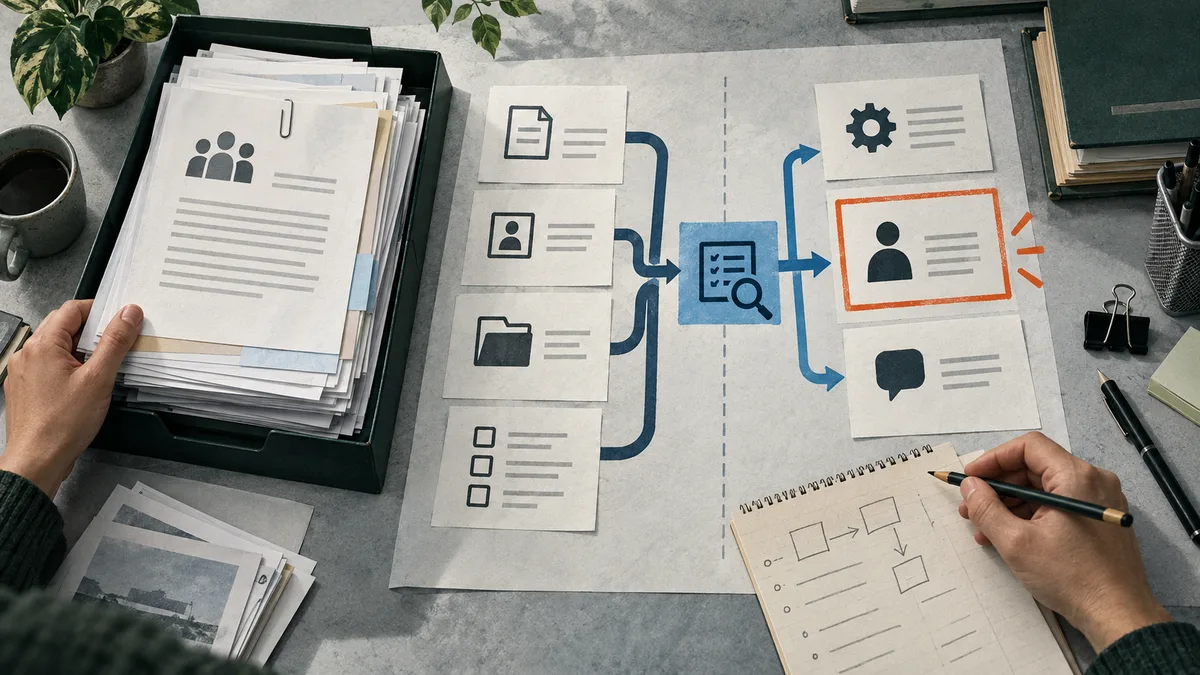
Yes, as a structured reflection aid. A public-benefits caseworker can describe document receipt, classification, data extraction, completeness follow-up, policy lookup, evidence interpretation, eligibility determination, and applicant explanation as separate tasks. The AI Proof Work checker can return task-level change-pressure signals that help frame which tasks merit a closer look. It cannot verify that an agency has adopted a tool, establish that a tool is accurate or authorized, decide whether a task can legally be automated, or estimate whether a worker will lose a job. Use it to sharpen a workplace question, not to audit an agency or predict a person's employment.
Can the checker separate document intake from eligibility judgment?
Two readings of a caseworker's day can both sound plausible. One is that the role is a single process called “processing applications,” so anything that touches an application appears equally exposed to automation. The other is that the role contains a chain of distinct tasks: receiving a document, identifying it, checking whether a field is present, asking for a correction, comparing evidence with a program rule, deciding what the evidence means, and explaining the outcome. The second description is more useful for a task checker because it lets the worker examine the work at the level where tools are designed and where responsibility can change.
The direct answer is yes, with a boundary. The free AI Proof Work checker can help a worker enter recurring tasks separately and see transparent change-pressure signals for those descriptions. It is a structured way to ask, “Which parts of my week involve repeatable digital inputs, and which depend on interpretation, contact, or accountability?” It does not inspect the worker's actual files, agency systems, local rules, procurement decisions, permissions, quality controls, or staffing plans. Its output is not an operational assessment and not a validated probability of redundancy.
That distinction matters especially in public benefits. Document handling can appear clerical while affecting whether a person receives a timely opportunity to prove eligibility. Conversely, a task can involve a complex rule but still be supported by a narrow retrieval tool that points a worker to a source without deciding a case. Labels like “intake,” “judgment,” “clerical,” and “AI” do not settle the matter. The practical question is what the worker does, what a tool would produce, how that output enters the process, who checks it, and what happens when it is wrong.
This guide works through one bounded comparison: a U.S. government benefits caseworker entering a whole-job description, a bundled application-processing task, or a separated list of work steps. It uses public occupational descriptions, federal policy guidance, research and pilot materials on benefits tools, and evidence about administrative systems. Those sources can clarify the task map and the stakes. They cannot tell an individual worker whether their office is using AI or planning to change staffing.
The useful conclusion is modest but actionable: separate the tasks before interpreting the signal. Use only generic task descriptions in the checker. Then take the task with the clearest real-world friction or change and ask an authorized supervisor or agency AI lead what systems, rules, review steps, and evidence apply. The checker can help formulate that question; the answer must come from the work setting.
Sources: Eligibility Interviewers, Government Programs (43-4061.00); Public Benefits and AI
What exactly belongs in the task description?
Start with a description of work that someone could observe, not with a job title or a forecast. “Eligibility interviewer” is useful for locating an occupational family, but one worker may spend a large share of a week on appointments, while another may spend more time reviewing documents or resolving discrepancies. The same title can cover different programs, caseloads, office procedures, seniority levels, and local systems. A task checker cannot infer that local mix from the title alone.
The U.S. Department of Labor-sponsored O*NET profile for Eligibility Interviewers, Government Programs (43-4061.00) lists tasks that already demonstrate why the bundle should be split. It describes compiling, recording, and evaluating personal and financial data to verify completeness and accuracy and determine eligibility status. It separately describes interviewing applicants, investigating information, and explaining requirements and legal rights. This is occupational taxonomy, not a diary of any worker's week, and it does not measure AI exposure. But it makes clear that intake and judgment are distinct pieces of the occupation's work.
The Bureau of Labor Statistics' Information Clerks profile offers another useful contrast. It describes routine record and data tasks among information clerks and scanning or uploading among file clerks; it describes eligibility interviewers as asking questions to determine whether applicants qualify for benefits, providing program information, and referring people to other services. These descriptions can help a reader name tasks in plain language. They should not be used to assume that a caseworker's job is equivalent to file clerking or that tasks are interchangeable across agencies.
A practical task list might begin with eight verbs: receive, classify, extract, check, follow up, retrieve, interpret, decide, explain. For example: “I open submitted proof-of-income documents and identify their type”; “I enter dates and amounts into an approved case system”; “I check which required item is missing”; “I contact an applicant to request a correction”; “I locate the current program rule”; “I compare conflicting records”; “I make or recommend an eligibility determination under the applicable process”; and “I explain what is needed next.” Each description should be narrow enough that a colleague could say whether it happens and what output it creates.
If a task is infrequent, separate it only if it matters to the decision. If several steps always happen together, describe the bundle first, then split the points where either the input, the judgment, the responsible person, or the consequence changes. “Process an application” is too broad to tell whether a tool would scan a file, flag a missing field, interpret a program rule, or recommend a decision. Conversely, splitting every click into a separate task creates noise. The goal is not maximal granularity; it is a map that makes different kinds of work visible.
For each entry, write down how often it occurs, what triggers it, what information is used, what a correct output looks like, and what the worker must do when information is unclear. A worker can keep this record privately and in non-sensitive terms. Do not paste names, case narratives, income records, benefit IDs, immigration records, health information, or other applicant data into a public checker or unapproved tool. A task description can say “compare document dates against a checklist” without revealing a person's circumstances.
Then distinguish the work from the tool question. A task may be digitally repeatable in principle yet unsuitable for automation in a particular program. A task may be time-consuming but have no authorized tool. A tool may be technically capable of extracting text yet fail on images, handwriting, language variation, or missing pages. Listing a task helps clarify what to investigate; it does not establish any of those facts.
Sources: Eligibility Interviewers, Government Programs (43-4061.00); Information Clerks: Occupational Outlook Handbook
Which intake tasks look technically addressable, and where does that stop?
Document intake contains several different operations that are easy to blur together. A system might convert a scanned page into searchable text, sort pages into document types, extract a date or dollar amount, compare the extracted field with a checklist, or draft a request for a missing item. Each operation has a different output and failure mode. Calling all of them “document review” hides the question that matters: what is the system being asked to do, and what decision or action follows from its output?
The U.S. Department of Health and Human Services' Public Benefits and AI plan identifies examples of assistive work such as scanning paper documents, summarizing case files, drafting material, and retrieving policy information while directing staff to check the source. The plan also discusses processing application inputs for completeness or accuracy and eligibility-related activities as potentially rights- or safety-impacting uses. Its classification depends on how a tool operates and affects people. It is federal risk guidance for relevant programs, not a statement that all document support is prohibited or that any given task is safe because a person remains in the loop.
Nava Labs' 2024 case study gives a specific illustration. In SNAP-focused experiments, the team tested identifying and categorizing document types, extracting required information, and giving document-quality feedback against program documentation requirements. The case study describes a prototype that appeared promising for its tested document tasks and reports positive reactions from navigators and applicants. It also says further testing was needed on whether the system could apply more nuanced program rules while categorizing documents. These are experiments and prototype findings in a defined setting, not a production accuracy guarantee for all documents, states, programs, or workers.
That example supports a narrow proposition: document classification and field extraction are plausible candidates for task-level examination. It does not support the claim that eligibility decisions can be safely automated, that a worker's intake role is already being automated, or that case staffing will fall. It also does not show whether an individual office has approved a tool, connected it to its records, tested it on its own documents, or established a process for correcting errors.
Consider a document with a clear printed employer name and pay date. A system might identify the page as a pay statement and extract those fields. The worker may still need to check whether the document belongs to the right household member, whether the pay period matches the requested period, whether the amount is gross or net, whether pages are missing, and whether the applicable rule calls for a particular calculation. The initial extraction can be a useful intermediate output without being the answer to eligibility.
Now consider an intake check that marks a required document as absent because its file name is unexpected, its scan is rotated, or the applicant supplied an acceptable substitute. If a worker receives a prompt and can inspect the file and correct the classification before any notice or deadline changes, the task operates differently from a system that automatically closes a case or sends an adverse message. The same technical operation may have different stakes depending on what action it triggers.
A checker can help the worker identify these steps as candidate tasks and notice where digital repetition is present. It cannot test recognition quality, false positives, missed pages, language coverage, accessibility, or performance across document types. Those are questions for local evaluation using approved data, defined standards, and accountable owners.
Sources: Public Benefits and AI; Experimenting with AI-powered tools in public benefits
Why can the same task have different stakes?
The consequence comes from the whole workflow, not only the technical action. Reading a page, summarizing a file, or flagging a blank field may look like administrative support. But if that output affects which evidence receives attention, whether a worker requests more information, how an applicant understands a deadline, or whether a file moves forward, it can shape access to a benefit. A human click at the end does not automatically make the system's influence inconsequential.
HHS guidance is useful here because it distinguishes tools that support staff from systems that influence rights or safety. It explicitly gives an example where a tool recommending an eligibility decision for a caseworker to review and act on can count as rights-impacting, even though a human acts. Its examples and risk categories are tied to the guidance's scope and applicable program law. The lesson for a worker is not to classify a tool by the vendor's label, but to ask what outcome it influences and how much independent review is possible.
The OECD's 2024 paper on AI in minimum-income and unemployment assistance maps use cases from information provision through eligibility decisions and payment monitoring. Based on desk research, open-ended surveys, and semi-structured interviews, it discusses potential benefits such as timeliness and increased take-up alongside risks that include biased eligibility assessment and increased inequality. This is international policy analysis, not a survey of U.S. offices or evidence of an individual deployment. Its value here is to show that the same broad field includes very different functions and trade-offs.
A useful way to separate the stakes is to ask four questions. First, does the system merely transform an input, such as turning a scan into text, or does it assess whether a requirement is met? Second, does its output only help a worker locate information, or does it recommend a substantive conclusion? Third, can the worker review the underlying record, identify what was omitted, and override the output without penalty or delay? Fourth, what happens to the applicant if the output is wrong, late, or difficult to challenge? These questions do not replace legal review, but they make the task description more meaningful.
An extraction error and an eligibility error are not identical, but they can be connected. If an amount is copied incorrectly and the discrepancy is caught before action, the system has created rework. If the error changes a calculation, drives a request for the wrong document, or influences an adverse determination, the consequences grow. A checklist may be low stakes in a sandbox and high stakes when linked to an automatic deadline or closure. Therefore, “intake” cannot be treated as a blanket low-risk category.
The reverse is also important. Not every tool near a benefits process performs a decision. A search tool that points a worker to a current manual section can reduce navigation time while leaving rule interpretation to the worker, provided the source is visible and checked. A system that summarizes a call can aid recall while still requiring comparison with the recording or contemporaneous notes. Whether a function is appropriate depends on its actual design, evidence, controls, and context.
For task-checker use, this means not feeding one blended item such as “AI decides benefits.” Separate the underlying work and write down the effect of each output. That makes the signal easier to interpret without mistaking a description of possible exposure for a safety assessment.
Sources: Public Benefits and AI; Using AI to manage minimum income benefits and unemployment assistance
What does eligibility judgment add beyond a complete file?
A complete file is not the same thing as an eligible applicant. Completeness asks whether required information appears to be present and usable. Eligibility judgment asks what the relevant facts mean under a particular program's current rules, how to resolve inconsistencies, whether exceptions or procedural protections apply, and what conclusion the authorized process permits. Even when policy is codified, the facts may be incomplete, ambiguous, contradictory, or outside the usual pattern.
O*NET's occupational profile brings these elements together in a way that is useful for decomposition. Its task descriptions include checking personal and financial data for completeness and accuracy, determining eligibility status, interviewing applicants, conducting investigations, and explaining requirements and legal rights. That grouping does not mean every caseworker personally performs every function or that all have equal time weight. It does show that a task map should preserve the distinctions rather than reducing a role to “data entry” or “decision making.”
The OECD analysis describes how benefit systems can use data to support operations and notes the potential for AI to improve timeliness and take-up, while also raising concerns about bias and inequality. In some administrative settings, a worker may need to combine application information with other records or clarify how a rule applies. The source does not establish a universal workflow or that human judgment always improves accuracy. It does reinforce that a determination is embedded in data, rules, and institutions rather than being a simple extension of a document scan.
A useful comparison has three versions. Version A is “review benefit applications.” It conceals the full chain. Version B is “check whether a pay document is attached.” This is narrower but still fails to say what counts as attached, how substitutes are handled, and whether a missing flag leads to a consequential action. Version C separates file identification, field extraction, checklist comparison, follow-up, evidence reconciliation, rule application, determination, and notice. Version C is not automatically the correct technical design, but it makes the decision boundary visible.
The critical boundary may lie in an apparently small transition. A tool can indicate that a document appears to contain a date. A worker must decide whether that date corresponds to the requested period. A tool can compare an income amount with a threshold that is already expressed in a table. A worker or authorized process may still need to establish which household members count, how income is treated, and what exceptions apply. A generated explanation can sound clear while omitting a necessary qualification. The difference is not that people are always right and software is always wrong. It is that the work requires accountable procedures, evidence of performance, and a means of resolving uncertainty.
The checker's role is smaller than any of those operational questions. It can prompt the worker to distinguish tasks where the output is a transcription or search result from tasks where it shapes a material judgment. The worker can then ask whether an approved system already supports the task, whether errors are measured, and which decisions must remain with an authorized official under local rules. The checker cannot answer those questions itself.
This distinction is also useful for career reflection. If a worker's experience includes resolving conflicting records, explaining rules accessibly, coordinating with applicants, documenting reasons, and correcting errors, those are work contributions worth recording alongside repetitive steps. That observation is not a promise that such work is immune to technology or labor-market change. It is a more complete account of the skill bundle than a generic label such as “administrative.”
Sources: Eligibility Interviewers, Government Programs (43-4061.00); Using AI to manage minimum income benefits and unemployment assistance
What real public-benefit examples do—and do not—show
Public-benefit examples are useful only when their task, population, setting, and evidence are kept attached. Nava Labs' 2024 experiments concerned potential tools for benefit navigators and applicants, initially scoped around SNAP rules. The case study describes prototypes for document categorization, extraction, quality feedback, call-note summaries, policy questions, and referrals. Different prototypes had different results. The document prototype was described as promising in its tests, while referral output varied and the policy question chatbot required human review. This is a collection of project experiments, not a controlled test of all functions or an estimate of workforce change.
The later Nava Labs evaluation is a different piece of evidence. Its public summary describes an evaluation of an assistive benefits-navigation chatbot, including a randomized evaluation in which 125 caseworkers answered hypothetical questions and a 14-week quasi-experimental pilot involving 61 caseworkers across six organizations in Los Angeles County. Nava reports an estimated average 40% improvement in caseworker accuracy, with larger impact on harder questions, and says 65% of caseworkers with access reported real-world use. It also reports that results on administrative burden were inconclusive because of small sample size and varied experiences.
Those numbers need their nouns. They refer to caseworker accuracy on the study's benefit-navigation questions and a defined chatbot intervention, not document intake accuracy, eligibility adjudication, all caseworkers, or job retention. The pilot was limited to six organizations in one county, while the randomized component used hypothetical questions. The publication is a project report from the organization involved in developing the tool, with academic collaborators. It provides relevant evidence that one assistive tool can improve measured performance in its evaluated setting. It does not certify a different product or a local deployment.
The evidence can challenge both extremes. It challenges the claim that AI in this field is only hypothetical: a specific tool was evaluated with caseworkers and reported use during a pilot. It also challenges the claim that one positive evaluation means the whole job is automatable: the study focused on answering benefit-navigation questions, not replacing the caseworker's entire workflow. Results depended on the tool, question type, implementation, and context. A different task needs a different evaluation.
Nava's current Caseworker Empowerment Toolkit page lists an assistive chatbot, a form-filling assistant with caseworker oversight, a referral generator, a document analyzer, a call-note summarizer, and a work-requirements checker. Its public page describes tools being built and tested, including a document analyzer that checks whether documents meet requirements. That page can establish what the organization says it is developing; it is not independent proof of production deployment across agencies or of performance in any worker's office.
A worker should therefore record an example with four labels: task, setting, kind of evidence, and limitation. “A prototype tested SNAP document classification” is a meaningful statement. “AI now handles public-benefit eligibility” is not supported by that prototype. “A chatbot evaluation reported improved accuracy on benefit-navigation questions among studied caseworkers” preserves the measured outcome. “AI makes caseworkers more accurate” removes the boundaries and overstates the conclusion.
That discipline matters when using a checker. A task-level signal is a reason to ask what kind of work might be affected, not evidence that a similar system exists locally. Public examples can make questions concrete, but agency-specific facts must come from authorized local sources.
Sources: Experimenting with AI-powered tools in public benefits; Evaluating a GenAI-powered assistive chatbot for caseworkers
How should you read the checker's signal alongside adoption evidence?
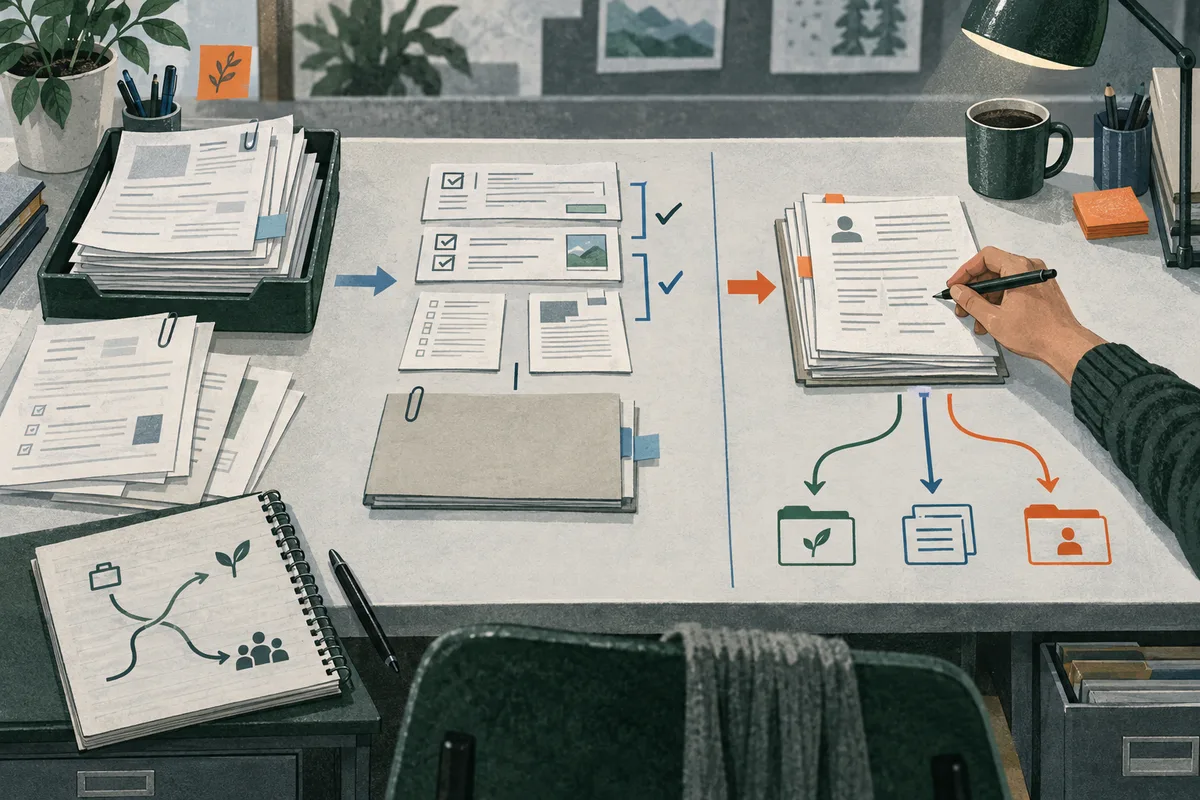
A task checker addresses a different question from an adoption inventory. A checker may indicate that a task description has features associated with change pressure. An adoption source would need to show that a particular organization selected, approved, deployed, and actually used a system for a defined purpose. Even documented use does not by itself show that the tool works well, changes job design, reduces labor demand, or displaces a worker. Each step requires its own evidence.
The U.S. Government Accountability Office's 2025 report on selected federal agencies provides context on government generative-AI activity and barriers. It reports that submitted inventory use cases across 11 reviewed agencies increased from 32 in 2023 to 282 in 2024. Officials also described challenges involving policy, privacy, budget, technical resources, and rapidly changing guidance. These are counts of reported use cases in selected federal agencies, not a count of employees, state benefits offices, production workflows, or eligibility systems. They show growth in reported experimentation or use within the inventory's scope, alongside constraints; they do not tell a public-benefits caseworker what their own employer has adopted.
The Nava materials offer more directly relevant examples, but still require care. One report covers prototypes and experiments; another describes a defined chatbot evaluation and pilot. The newer toolkit page lists tools and development phases. A project can move from prototype to pilot without becoming part of every office's approved workflow. A public case study can document a use in one setting without establishing broad adoption. For a worker, local policy, procurement notices, training, approved software lists, supervisor communications, and actual workflow changes are better evidence of local adoption than a general industry signal.
Use five separate columns when thinking about what the evidence says. Capability asks whether a system can perform the operation under specified conditions. Observed use asks whether people used it in a study or pilot. Organizational adoption asks whether an agency authorized and integrated it. Labor demand asks what employers hire for and what tasks they need. Displacement asks whether workers or positions are reduced because of the change. A study of capability cannot stand in for adoption; adoption cannot stand in for displacement.
Even “use” needs precision. A worker may try a tool for a voluntary draft without putting its output into a case record. Another system may be integrated into the case-management queue and shape which files staff review first. Both may be called AI use, but their influence differs. Similarly, an employee may save time on one task while the organization directs that time toward more complex cases rather than reducing headcount. That is a possible form of job redesign, not proof of a particular outcome.
The checker can help construct a list of questions from the worker's own task mix. For example: “I spend time identifying document types and copying fields. Has our agency evaluated an approved tool for those exact inputs? What error rate or review process applies? Does a flagged item affect case status before a person checks it?” These are questions, not implied claims that a system exists. A worker can also ask where to find the agency's policy and who owns the workflow.
If no local tool is in use, the signal may still be useful as a prompt to track changes or build transferable capability: careful data checking, clear process documentation, accessible communication, and the ability to explain where evidence comes from. But training choices should follow a concrete goal and employer policy. Buying a generic AI certificate is not automatically the best response. A small approved project or a conversation with a supervisor may provide more relevant information at lower cost and with less disruption to income or family plans.
Sources: Experimenting with AI-powered tools in public benefits; Evaluating a GenAI-powered assistive chatbot for caseworkers; Artificial Intelligence: Generative AI Use and Management at Federal Agencies; Information Clerks: Occupational Outlook Handbook
What can a checker never certify about an eligibility system?
A task checker cannot certify that an eligibility system is lawful, accurate, fair, secure, accessible, or appropriate. It does not know the program's governing rules, the agency's approved workflow, the source data, the system's version, the cases it has been tested on, the appeal process, or the identity of the accountable decision maker. A task-level output can help frame a discussion, but it has no authority over a case or a worker's duties.
The distinction between a worker's task and an agency system is especially important because public benefits decisions can affect access to food, health care, housing support, income, or services. HHS guidance notes that tools influencing a caseworker's eligibility decision can be rights-impacting, even if a caseworker reviews the output. That is why “human in the loop” is not a complete description of safeguards. The person needs sufficient time, source visibility, training, authority to disagree, and a workable route to correct a record or explain an error. Those conditions must be established in the specific process.
A 2026 Public Administration Review article, available through the publisher's abstract, analyzes 71 federal and state court dockets challenging algorithmic determinations in disability, unemployment, and nutrition assistance. The abstract describes failures linked to flawed data, design choices, and system limitations, and argues that administrative errors can arise across technical, organizational, and legal governance. A docket study is selected toward contested failures; it is not a representative estimate of how often all systems fail and does not evaluate generative document tools. It is evidence that error pathways can matter and that governance is not reducible to model performance.
That evidence points to operational questions a checker cannot answer: Are source documents retained and accessible? Can the worker see the exact input behind a summary? Is the tool's output logged? How are incorrect classifications corrected? Does the workflow test for differences across document formats, languages, disabilities, or applicant circumstances? Who can pause use if errors emerge? What notices explain the basis of an action and how to challenge it? Which program rules or collective agreements limit tool use? These questions require agency documentation and appropriate governance.
A simple task label can also miss whether people can contest a result. Suppose a tool extracts an address from a form. If the field is plainly displayed and the worker checks it against the source, the tool's error may be easy to catch. If an unseen classification changes routing or suppresses a follow-up, the error can be harder to notice. The difference lies in observability and process design, not in whether a task sounds routine.
Nor can the checker establish workforce consequences. The fact that a task has repeatable elements does not imply that an employer will automate it, that a system will be reliable enough, that time savings will eliminate a role, or that demand for the occupation will fall. A department might redeploy saved time, change case volumes, alter service standards, or make no change. A checker result cannot distinguish among these possibilities.
The safe interpretation is therefore precise: “This task description raises a question about where digital assistance may be relevant.” It does not mean “my casework is about to be automated,” “my job is safe,” or “the agency should use a tool.” If the question affects a live case or a high-stakes decision, follow approved procedures and raise it through the appropriate work channel rather than relying on a personal score.
Sources: Public Benefits and AI; How Do Algorithmic Decision-Making Systems Used in Public Benefits Determinations Fail? Insights From Legal Challenges
What can you learn without turning the checker into an agency audit?
A worker can learn quite a lot by mapping their own work, provided they keep the scope modest. The Georgetown Beeck Center's 2025 project on state benefits eligibility and enrollment systems describes interviews with 24 government employees across seven states and notes that research about system management, staffing, stakeholders, and technologies has been limited. It covers integrated systems serving programs such as SNAP, Medicaid, TANF, and child care. That small interview sample does not represent every state or prove anything about a particular agency, but it supports a practical point: local implementation details are not recoverable from a national job description or a generic task signal.
A worker's map can include task, frequency, input, output, decision point, review, and unresolved question. For example: “I receive uploaded wage records several times each day; I identify the document and check the covered period; an incomplete record leads to follow-up; a conflicting amount goes to a different review step; I do not use unapproved tools.” This is enough to prompt a useful discussion without exposing personal data or assuming a particular technology.
Next, separate what you know from what you infer. You may know that your office introduced a new queue, changed its document checklist, or assigned a designated reviewer. You may have heard that a vendor is being considered. You may infer that a task is technologically addressable because it involves typed fields. Mark these differently. A rumor, capability claim, observed use in another location, and approved local system are not the same evidence. Keeping the distinction explicit protects both the quality of your reasoning and your credibility at work.
Then identify the kind of uncertainty that matters most. Is it task allocation: how much time do you spend on intake versus applicant contact? Is it policy: which rule governs an acceptable substitute document? Is it tool performance: what happens with poor scans or multilingual records? Is it authorization: which tools may process confidential information? Is it job design: what would change in your duties if a task became faster? Each question has a different source of answer. A task checker is only useful for the first framing step, not as a substitute for local evidence.
An appropriate next step may be as small as reviewing a job description, approved software policy, training note, or procedural manual. If there is no approved tool, do not experiment with applicant information in a consumer service. If a pilot is authorized, ask what inputs are allowed, whether the tool stores data, how output is verified, who can override it, and how mistakes are reported. Those are ordinary due-diligence questions, not a claim that a pilot is underway.
For career planning, compare realistic options before committing money or time. If your goal is to work more effectively in the same role, start with agency-approved AI literacy and the workflow's rules for privacy and verification. If your goal is to document or improve intake processes, a small project with a supervisor may be more informative than an external credential. If you want to move into system oversight or procurement, identify the actual requirements in local job postings and speak with people in those roles before selecting a course. A degree may be appropriate for a target role that requires it, but it should not be the reflexive answer to a broad concern about AI.
The constraints matter. Preserve salary and benefits needs, location limits, caregiving schedules, health, tuition cost, and time for training. A worker who cannot take a full-time course may still build evidence of process expertise through a bounded, approved improvement project. A worker who cannot change agencies may look for adjacent responsibilities in quality assurance, training, policy operations, or service design if those are available locally. These are options to investigate, not guaranteed pathways or universally safe roles.
A compact personal record can track changes over time: tasks performed, systems actually used, review steps, skills practiced, and questions answered. Avoid collecting case-level information or confidential screenshots. This record helps separate a real change in your work from generalized headlines and can support a grounded conversation with a supervisor, union representative, or career adviser, depending on your context.
The main value of the checker is that it may reveal a better question than “Will AI replace caseworkers?” You can ask whether repetitive document classification is changing, what evidence supports the change, what parts remain accountable human work, and which capabilities would help you adapt. That is a decision you can investigate without pretending to know the future of employment.
A short worksheet can keep the exercise disciplined. For each recurring task, write one sentence about the input and one about the output. Note whether a person currently checks the output against its source, what happens when information conflicts, and whether the next action affects an applicant's deadline or case status. Then add a column for evidence: direct observation, written procedure, formal agency notice, or an unverified impression. This is not a new scoring system. It is a way to keep a technology possibility from being mistaken for a workplace fact.
For instance, “classify submitted documents” becomes clearer when the worker records whether the files are scanned or digital, whether a checklist defines acceptable document types, whether substitutions are permitted, and who handles a mismatch. None of those details needs a client name or case excerpt. The worker can ask a process owner about the rules instead of uploading a document to see whether a system recognizes it. That protects privacy while still making the work concrete enough to discuss.
If a supervisor confirms that an approved pilot is planned, the next useful question is not simply whether the tool is accurate. Ask accurate for which document types, under what conditions, and measured against what reference? Ask whether performance has been checked on low-quality scans, unusual but valid documents, and the languages used by the service population. Ask what an operator sees when the system is uncertain, whether a confidence display has been validated, and how a disagreement is recorded. A tool that reports uncertainty clearly may support review differently from one that produces a confident but unsupported answer.
Finally, ask what success would mean for both applicants and staff. Faster handling alone may not be enough if it increases incorrect requests, creates a new review burden, or makes explanations harder. A local evaluation could examine completion time, correction rates, missed evidence, applicant follow-up, and worker ability to verify outputs, subject to the agency's own legal and privacy requirements. A checker cannot design that evaluation, but separating tasks helps a worker point to the right operation and outcome.
Sources: Implementing Benefits Eligibility + Enrollment Systems: A Review of State Practices; Eligibility Interviewers, Government Programs (43-4061.00); Public Benefits and AI
Ask one focused question about the workflow
The verdict is that the AI Proof Work checker can help a U.S. public-benefits caseworker examine document intake separately from eligibility judgment, if the worker enters specific recurring tasks rather than treating a job title as a single unit. The distinction is supported by occupational descriptions that include both data checking and eligibility work, by HHS guidance that ties risk to how a tool influences outcomes, and by public-benefit examples that test different functions separately. The checker adds a structured reflection signal; it does not establish local adoption, operational suitability, legal authority, or job displacement.
The strongest reason for caution is that intake is not necessarily low stakes. Missing or misread information can alter whether an applicant gets follow-up, whether the case moves forward, or what a later decision relies on. At the same time, a documented assistive use does not mean the whole job is being automated. The 2026 Nava evaluation of a benefit-navigation chatbot reported a bounded accuracy improvement in its studied setting, while its sample, intervention, outcomes, and pilot context limit how far the result can travel. Both points can be true: specific assistance can be valuable, and broader conclusions require more evidence.
For an individual worker, the first recommendation is to map the actual task chain using plain verbs and no applicant information. Second, compare the map with approved local procedures and separate confirmed tool use from speculation. Third, choose one task with a concrete question about its input, output, review, or consequence and raise it through an authorized channel. Do not infer a redundancy forecast from change pressure, and do not upload confidential records to learn what a public checker says.
This approach keeps experience in view. It recognizes repetitive work without reducing the job to repetition, and it recognizes judgment without treating judgment as beyond technological change. What deserves attention is the combination of task, stakes, evidence, authority, and worker constraints. A caseworker may decide to learn an approved tool, document an intake process, seek a small quality-improvement project, explore an adjacent role, or simply wait for clearer local evidence. The right move depends on goals and circumstances, not a universal instruction to retrain.
If you use the checker, consider the free task-level result a starting point for reflection. The paid career roadmap is a separate option for someone who wants to compare a stay-and-redesign path, adjacent moves, and a larger change against experience, salary floor, geography, time, and personal constraints, with a 30/60/90-day plan. It cannot guarantee employment or income and is not professional counseling. Neither tool should be treated as an agency audit or an employment decision instrument.
A useful conversation can begin with one precise question: “For document intake, which approved steps are changing, what evidence shows the tool handles our actual documents reliably, and where must a caseworker still review or resolve the result before it affects an applicant?” That question keeps the discussion on the workflow, makes uncertainty explicit, and gives the worker a basis for deciding what to learn or do next.
Sources: Eligibility Interviewers, Government Programs (43-4061.00); Public Benefits and AI; Experimenting with AI-powered tools in public benefits; Evaluating a GenAI-powered assistive chatbot for caseworkers
Questions readers ask
Does a high task change-pressure signal mean my caseworker job will disappear?
No. The checker describes task-level change pressure, not a validated probability of job loss. It does not know whether your agency has adopted a tool, how work will be redesigned, or what happens to staffing.
Should I enter a case file to see how exposed my work is?
No. Describe recurring tasks in general terms. Do not submit applicant names, records, case narratives, income details, or other confidential information to a public checker or an unapproved system.
Is document intake less important than eligibility judgment?
Not necessarily. A document-classification or completeness error can affect follow-up and case progress. The stakes depend on how an output is reviewed and what action follows, so intake should be analyzed separately rather than assumed harmless.
Should I get an AI certificate to prepare?
Only if it supports a specific goal and fits your constraints. For an existing public-benefits role, begin with agency-approved training and the workflow's privacy and verification rules; consider a bounded, approved project before paying for a credential.
Sources and notes
- Eligibility Interviewers, Government Programs (43-4061.00)
O*NET's occupational profile separately lists evaluating personal and financial data for completeness and eligibility status, interviewing and investigating applicants, and explaining requirements and legal rights; it describes occupational tasks, not any individual worker's task mix or AI exposure.
- Information Clerks: Occupational Outlook Handbook
BLS describes file-clerk scanning and record work separately from eligibility interviewers' qualification questions, program information, and referrals; its 2025–35 table projects 2% employment growth (2,600 jobs) for eligibility interviewers, government programs. These are national occupational descriptions and projections, not local hiring or an AI displacement forecast.
- Public Benefits and AI
HHS's plan treats application processing and eligibility determination as distinct use areas and discusses rights- or safety-impacting uses, including eligibility-related functions; examples and categories apply within the plan's stated scope and do not establish a particular office's tool use.
- Using AI to manage minimum income benefits and unemployment assistance
The OECD report reviews AI uses in minimum-income and unemployment assistance and discusses potential service benefits and risks such as biased assessment and inequality; it is international policy analysis, not evidence of deployment in a particular U.S. office.
- Experimenting with AI-powered tools in public benefits
Nava reports a SNAP-focused prototype experiment involving document identification, categorization, data extraction, and feedback against documentation requirements, and says further testing of nuanced rule application remained; findings are specific to those experiments, not general production performance.
- Evaluating a GenAI-powered assistive chatbot for caseworkers
Nava reports an estimated average 40% accuracy improvement for its assistive benefits-navigation chatbot in a defined caseworker evaluation, alongside a 125-caseworker hypothetical-question evaluation and a 61-caseworker pilot; this outcome concerns that intervention and studied questions, not document intake accuracy or general workforce effects.
- Artificial Intelligence: Generative AI Use and Management at Federal Agencies
GAO reports that generative-AI use cases in inventories from 11 selected federal agencies rose from 32 in 2023 to 282 in 2024 and identifies reported implementation challenges; these counts do not measure state or local eligibility-office adoption, production use, or workforce effects.
- How Do Algorithmic Decision-Making Systems Used in Public Benefits Determinations Fail? Insights From Legal Challenges
The publisher record and abstract describe qualitative analysis of 71 federal and state court dockets contesting algorithm-based decisions in disability, unemployment, and nutrition assistance, illuminating alleged error pathways; the litigation-based sample is not a representative failure rate or an evaluation of generative document tools.
- Implementing Benefits Eligibility + Enrollment Systems: A Review of State Practices
The Beeck Center project page reports interviews with 24 government employees across seven states that operate or are building integrated eligibility and enrollment systems; this limited sample illustrates implementation variation but does not represent every state or a specific agency.
Apply this to your own work
See the whole job market at once.
Explore which occupations AI may reshape, then turn the signal into a practical response.
Explore the job map