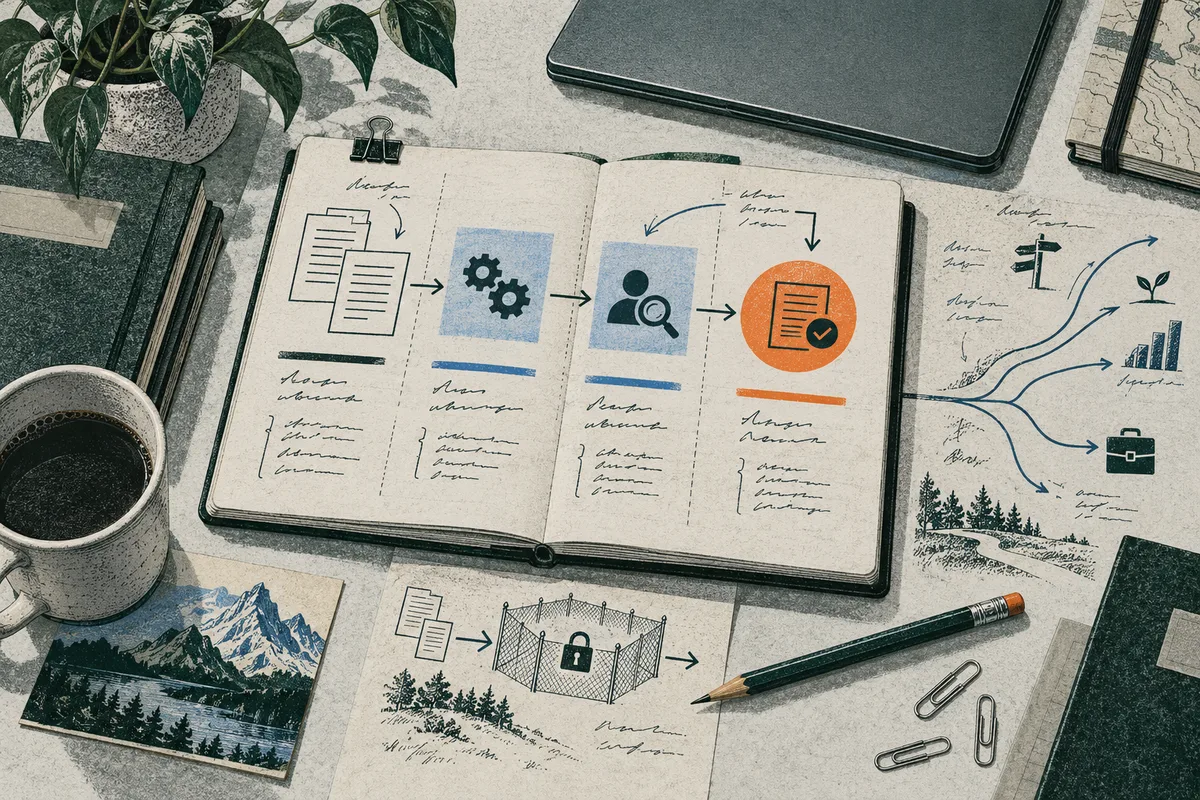
Choose one repeated analyst task with a checkable output, and confirm that the exact tool, account, task, data category, and handling conditions are approved before using client material. If approval is unclear, rehearse with independently created synthetic examples or permitted public information. Compare matched examples with the current workflow, counting review and correction time as well as errors. A rehearsal can test task mechanics, but cannot establish client-data safety or production readiness.
The short answer: approve the boundary, then test one task
Choose one repeated analyst task with an output you can check, then ask: Is this tool, account, task, data category, and set of handling conditions approved? If the answer is unclear, keep client material out. Rehearse with independently created synthetic examples or public information permitted for this purpose. That can reveal whether instructions produce a usable format, how much checking takes, and which errors are easy to spot. It cannot establish that client records may be submitted or that the workflow is ready for production. Compare the ordinary and assisted processes on closely matched examples and the same output standard. Count preparation, prompting, checking, correction, and handoff time; record quality and material errors alongside speed. The NIST AI Risk Management Framework: Generative AI Profile treats data privacy as a risk to manage. The NIST AI RMF Playbook’s measurement guidance calls for documenting tests and their limits. These are frameworks, not approval for a dataset or proof that a short trial will generalize. Keep interpretation, source verification, and sign-off with the analyst. Start with one bounded task, learn what the evidence supports, and advance only when policy and results allow it.
Sources: NIST AI 600-1: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile; AI RMF Playbook: Measure
What has to be approved before the clock starts?
Before the first prompt, get an answer about the proposed use, not a general assurance that “AI is allowed.” Approval needs to cover the actual service and account, the task you intend to perform, the category of information involved, and how the material will be handled. Ask whether approval covers prompts, files, outputs, logs, retention, and access. Start with the person or team that owns the work and data. This may be your manager, data owner, security or privacy contact, or designated approver. Ask who can decide and which policy governs. If authority is unclear, ask IT or security where approval requests go. A colleague’s use or a product demonstration does not authorize your client material. Record the approved account, task, data types, safeguards, reviewers, and exclusions. This preflight is warranted because privacy and confidentiality are separate questions from whether a tool can perform the task. NIST’s *Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile* identifies data privacy impacts that include leakage and unauthorized use or disclosure of personal or sensitive information. This voluntary cross-sector framework is not an incident-rate study or ruling about your employer’s files; it names a risk but grants no permission. Client information may also be commercially sensitive or contractually restricted even when it is not personal data. Likewise, a work login or a product tier does not answer the authorization question by itself. The OpenAI Help Center’s *Data access for your managed ChatGPT account* explains that an organization may manage account data, features, retention settings, and workspace controls. Depending on the organization’s configuration and applicable law, an administrator may be able to access, export, audit, retain, delete, or control submitted prompts, files, and outputs. Organization policies and administrator permissions apply in a managed workspace. This guidance covers ChatGPT only; it establishes neither controls for other services nor approval to process client records. Verify the actual account and settings rather than inferring them from a “business” or “enterprise” label. If the answer is no, delayed, or ambiguous, keep client material out of the trial. Rehearse with independently created synthetic examples or permitted public information, and label the result a rehearsal. That can help you assess whether instructions are clear and whether outputs are reviewable, but it cannot establish that client-data use is authorized or safe. Do not copy a real row and merely remove its name unless the organization has approved that transformation and use. If a representative example would reuse protected details, stop and ask the data owner. Write down the boundary before testing: what is approved, what must not be entered, which account to use, who reviews outputs, and where to report an accidental submission. If information does go into a tool contrary to policy, stop further use and follow the organization’s incident-reporting process; deleting a chat does not settle the issue. The immediate decision is simple: proceed with only the specifically cleared inputs, or run a lower-fidelity rehearsal without client data while permission is unresolved. Either path lets you learn something without confusing vendor capability or account access with organizational authorization.
Sources: NIST AI 600-1: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile; Data access for your managed ChatGPT account
Does removing names make client data safe to test?
No. Removing a name can lower a route to identification, but it does not establish that a client record is anonymous or approved for use in an AI tool. If the organization has not approved the transformation and the later use, build an example independently or choose public information that is permitted for the task. This keeps the trial moving while preserving a firm boundary: a worker’s ability to edit a file is not evidence that the resulting file can be sent to a service. This keeps the trial moving while preserving a firm boundary: a worker’s ability to edit a file is not evidence that the resulting file can be sent to an external or internal service. In its UK GDPR guidance, the Information Commissioner’s Office (ICO) describes anonymous information as information that does not identify a person either on its own or when combined with information from other sources. It describes pseudonymization as replacing direct identifiers, such as names, with a reference number while a person may still be identified using additional information held separately. Under that guidance, pseudonymous information remains personal data. The test is not whether a colleague unfamiliar with the spreadsheet can guess the name at a glance; it is whether identification remains possible in the relevant setting, including with additional information available to the organization or recipient. Identification can also come from details that seem incidental. The ICO’s example concerns health records: even after names and addresses are removed, approximate treatment dates and locations, treatment types, approximate ages, or other distinguishing features may allow someone to be re-identified by linking the record with other information or deducing who it describes. The practical point is that risk depends on information and context together, not just whether a name column remains. A known project timeline or publicly discussed event may make a detail more distinguishing. A tiny client pool, known project timeline, or publicly discussed event may make a detail more distinguishing than it would be in a large unrelated dataset. The ICO’s legal explanation is specific to the UK data-protection framework and identifiable living people. It does not decide whether a dataset may be shared under a client contract, confidentiality duty, trade-secret rule, sector requirement, or another jurisdiction’s law. NIST’s Generative Artificial Intelligence Profile also identifies privacy risks including leakage and unauthorized disclosure. It is risk-management guidance, not an incident-rate study or permission to submit a dataset. For this trial, use a clear rule: do not copy, redact, code, aggregate, or otherwise transform client material for an AI test unless the organization’s responsible approver has authorized that processing and the proposed use. If the answer is unclear, stop at a fresh synthetic example or permitted public data. Label it clearly as a rehearsal, not approval to use real records.
Sources: Introduction to anonymisation; NIST AI 600-1: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
Which task is narrow enough to test fairly?
Choose one recurring task with an output you can describe beforehand, and a reliable way to check it. The trial asks whether assistance fits this slice of work, not whether an analyst’s occupation can be automated. A broad goal such as “use AI for analysis” combines finding data, reconciling it, deciding what matters, explaining uncertainty, and advising someone what to do. If the result disappoints, that scope makes it hard to identify whether the cause was the input, tool, prompt, checking method, or task. A bounded task gives the comparison a clear question.
Look for a repeatable transformation rather than a decision that depends on hidden context. An analyst might test turning a permitted public-data update into a standard table with source notes, or producing a first-pass explanation from figures already cleared for this use. The analyst would still check figures, decide which comparisons matter, and own any interpretation or recommendation. These are examples of task shapes, not evidence that a particular tool will perform them well. Keep the test away from client advice, consequential calculations, or final sign-off unless that use is specifically approved and review controls are adequate.
Before the first prompt, write a task card. State the permitted input and source, output format, required standard, and authoritative material for checking. Add known exceptions, the reviewer, and a stop condition. A pass standard might require each reported figure to reconcile to a named source, uncertainty to be surfaced, and unsupported claims to be absent. Define a material error for this task; a typo and a wrong figure do not carry the same consequence. If no one can identify a trustworthy source or competent reviewer, the task is not ready.
The NIST AI RMF Core says organizations should specify and document an AI application's scope and define human-oversight processes in line with policy. This is risk-management guidance, not proof that a task design will catch errors or permission to use a dataset. The Australian National AI Centre’s “Redesign your workflow” guidance also describes assigning AI and people distinct responsibilities, with people checking accuracy, handling exceptions, and retaining key decisions. These sources support explicit roles and checks; they do not establish that a two-week test improves productivity. Separate draft production from judgment and accountability in the trial plan.
Reject a task if a plausible error could escape review and cause harm before anyone can intervene. Narrowing does not mean pretending the work is simple: include checking and handoff, while keeping client material outside the test unless its use is approved. A task is ready when you can say what goes in, what comes out, how correctness is checked, who remains responsible, and when to stop. If those answers are vague, clarify the workflow or choose a smaller, lower-consequence slice. That keeps the trial interpretable while preserving the analyst’s domain judgment.
Sources: AI RMF Core; Redesign your workflow
What can a synthetic-data rehearsal show—and what can it not?
A rehearsal with independently created synthetic examples or permitted public information can answer a narrow question: can this tool perform the requested transformation in a form the analyst can inspect? It can show whether instructions produce the needed fields, whether a draft follows a format, and whether the sequence of prompting and checking is workable. Those are useful observations about task mechanics. They are not evidence that the tool is safe for client data, that the same quality will hold on actual records, or that the workflow is approved for operational use. The difference is fidelity. A deliberately simple example makes it easier to see whether a requested step works, but it may omit the conditions that make the real task difficult: inconsistent source files, unusual combinations of facts, missing context, edge cases, or the handoffs and integrations around the work. NIST’s AI Risk Management Framework Playbook recommends documenting test sets, metrics, procedures, and materials, and cautions against extrapolating from narrow or anecdotal assessments. A clean result supports a statement about those examples and that setup, not a broad claim about performance. Construct examples from scratch around the task’s structure. An illustrative dataset can use invented rows and a known answer so the analyst can check whether an output reconciles. Include ordinary cases and a few plausible complications, then keep an answer key or authoritative reference outside the model’s output. The point is to test whether the result can be checked, not to make a synthetic file look like a client file. Record important features deliberately left out, such as unusual formats or exception handling, so they do not disappear from the final interpretation. Do not create the rehearsal by taking a client row, deleting its name, and changing a few visible details. The Information Commissioner’s Office guidance on anonymisation explains that removing direct identifiers can leave distinguishing details that allow identification, and that pseudonymized information remains personal data in its UK GDPR framing. The guidance concerns identifiable people under UK data-protection law; it does not settle contractual confidentiality, commercially sensitive information, sector rules, or requirements elsewhere. NIST AI 600-1 also identifies privacy risks such as leakage, unauthorized disclosure, and de-anonymization. Neither source quantifies the risk for this particular tool or grants permission to process a transformed client record. The practical boundary is therefore straightforward: unless the organization has approved deriving and using such material, do not use it in the rehearsal. A synthetic rehearsal can still be worthwhile when client-data approval is pending. It can help the analyst refine the task definition, identify review steps, note obvious failure modes, and prepare a specific request for the next authorized evaluation. Keep the conclusion proportionate: “the format and checks worked on these constructed examples” is supportable if that is what was observed. “It works on our client records” is not. A positive rehearsal earns a request for an approved next stage; it does not turn synthetic inputs into permission to submit client files.
Sources: AI RMF Playbook: Measure; Introduction to anonymisation; NIST AI 600-1: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
How do you compare the old and assisted workflow fairly?
A fair comparison asks whether assistance improves the whole task under the same standard, not whether its first draft looks faster. Define the required output and checks before starting. Choose comparable examples with similar length, input quality, number of figures, and ambiguity. Pair irregular work afterward and note the basis. Keep awkward cases; selecting only clean or showcase examples distorts the local picture. For each example, time both methods from the same starting point to a usable handoff. Include input preparation, instructions, reruns, waiting when it blocks other work, source checking, correction, and final formatting. Apply one rule for active and elapsed time. If the analyst can work during a response delay, record that delay separately and use the same convention throughout. A quick draft may still make the complete workflow slower once review and repair are counted. Use a short rubric agreed in advance. Check factual fidelity, reconciled calculations, completeness, format, and unsupported claims. Compare both outputs with the same authoritative source, since the ordinary method can also err. Separate material errors from cosmetic edits. Note whether material errors were easy to catch or required specialist judgment. A polished tone is not evidence of correctness. If no reliable source of truth or competent reviewer is available, the trial cannot establish that consequential errors are being controlled. The National Institute of Standards and Technology’s “AI RMF Playbook: Measure” recommends documenting test sets, metrics, procedures, and materials, and assessing external validity: how far results from one context generalize to another. These are risk-management recommendations, not a validated recipe for a personal workplace comparison. They support recording examples, scoring rules, conditions, and deviations. They do not prescribe a sample size or make a two-week result representative. Keep a simple contemporaneous log: privacy-safe example label, method, time by stage, rubric results, material errors, corrections, and unusual conditions. Note prompt revisions and when they occur. Otherwise, later assisted cases may benefit from better instructions while the baseline stays fixed. Freeze a reasonable prompt, or mark a deliberate revision and compare periods separately. Record interruptions and unusual input quality. “How to run a two-week AI tool trial before you commit” at Good Transformer describes a bounded trial with a task, baseline, and go/no-go threshold, while noting that tools spanning systems or requiring new habits may need longer. This is commercial practitioner guidance, not independent evidence that two weeks suffices for an analyst’s task. Set a decision threshold before reviewing results: required quality is met, material errors are caught, and total effort is acceptable. That threshold is local, not a universal benchmark. At the end, state which examples, workflow version, and checks were covered, and what remains untested. A small comparison can reveal friction and recurring failure modes. It cannot remove learning effects or establish client-data performance from synthetic inputs. Use the result to decide whether to stop, adjust the task or rubric, or request authorization for a separate next stage. A faster draft matters only if the checked, corrected work serves the analyst’s purpose better.
Sources: AI RMF Playbook: Measure; How to run a two-week AI tool trial before you commit
What should the analyst verify, and who owns the result?
The reviewer should check the work against a source that can settle the question, not against how convincing the answer sounds. For a calculation, reconcile figures to the approved table and confirm units, periods, and formulas. For a summary, trace material statements to the underlying document and flag what is absent, ambiguous, or contradicted. For a structured output, check required fields and treatment of missing values. These checks require access to the relevant source and knowledge of which version governs. Set the rubric before looking at results. Decide which failures are material: a typo may be cosmetic, while a changed amount, invented explanation, omitted exception, or unsupported conclusion may make the output unusable. The threshold depends on the task and consequences; do not borrow a generic “mostly correct” standard. NIST’s AI Risk Management Framework Core calls for defining application scope and documenting oversight in line with organizational policy. It is guidance, not a ready-made checklist or proof that a particular review catches every error. Make ownership explicit before processing the first example. Name who checks each output, who can stop the trial, who handles an exception, and who approves consequential or client-facing use. The person accountable for the work product remains responsible for interpretation and sign-off unless policy assigns a different control. Responsibility should be assigned and understood, not implied by a review step. The Australian National AI Centre’s “Redesign your workflow” guidance recommends clear roles, checks, feedback, and exception handling. NIST’s Core also treats oversight as something to specify and document, not a label that makes a process safe. A reviewer needs authoritative material, enough subject knowledge to challenge the result, time for checks, and a route to escalate uncertainty. If any is missing, record the gap and narrow the task or pause it. A quick glance at polished prose is not meaningful verification. Log accepted, corrected, and rejected outputs, the reason for each decision, and time spent checking and repairing them. Note whether an error was easy to catch from the source or required specialist judgment; this shows where the workflow transfers effort to the reviewer. The Australian guide recommends feedback loops, while NIST’s “Measure” Playbook advises documenting test sets, metrics, processes, and materials. Neither validates this log as a productivity measure. Treat it as a practical record of the tested workflow, not an estimate for a whole team or future cases. Review capacity is part of the task’s cost. Include preparation, prompting, checking, correction, and handoff time in the comparison with the ordinary process. If a draft is faster but takes longer to substantiate, the trial has not shown a net time gain. If checks uncover errors that cannot be resolved from approved sources, stop or redesign instead of treating the reviewer as an unlimited safety net. Continue only if output quality is acceptable and the organization can sustain the review. Before each check, identify the source of truth and the failure that would change the decision. If a result cannot be traced, mark it unresolved rather than filling the gap from memory.
Sources: Redesign your workflow; AI RMF Core; How to Prepare Your Team to Use AI: Two-Week Pilot Plan
How should the two weeks be paced?
Treat ten working days as a manageable schedule, not a scientifically validated sample size. The calendar should prevent starting before the data boundary is clear or deciding from one memorable demonstration. “How to run a two-week AI tool trial before you commit” proposes a two-week test with a task, baseline, and decision threshold set in advance. That is planning advice, not evidence that ten days is sufficient for every analyst task. Workflows involving several systems, rare cases, or new habits may need longer. On days one and two, settle conditions before trying the tool. Confirm the service and account, task, permitted information, and handling rules with the responsible approver. If permission for client material is absent or uncertain, use independently created synthetic inputs or public information permitted for this purpose, and label the exercise a rehearsal. Define one recurring task with a checkable output, identify its authoritative review source, and record how the usual process handles a comparable example. Write pass criteria and stop conditions now: decide what counts as a material factual error, which fields must reconcile, and what review time is acceptable. These are local criteria, not universal thresholds. During days three through eight, work through a modest set of ordinary examples and include awkward but plausible cases, such as incomplete inputs or an exception that should be flagged. Apply the same output standard to the existing and assisted processes. Log preparation, prompting, review, correction, and handoff time consistently; a quick draft may only move effort into checking. Record material errors, unsupported additions, omissions, and exceptions separately from cosmetic edits. Note changes to prompts or procedures so improvement is not mistaken for performance under the original setup. Avoid choosing only easy examples or changing success criteria after seeing results. NIST’s “Measure” Playbook recommends documenting test sets, metrics, processes, and materials, and cautions against assuming narrow or anecdotal measurements generalize. This remains a local observation, not a representative study. On days nine and ten, compare the log with the criteria set at the start. Did outputs meet the task standard? Did review catch important errors? Was total effort acceptable? Identify missing examples and untested conditions. “How to Prepare Your Team to Use AI: Two-Week Pilot Plan” recommends a written plan, verification checks, and review based on recorded outputs; it describes its method as professional guidance, not a measured accounting-firm outcome. Use that as structure, not proof of likely results. Choose among stopping, redesigning the task, or requesting approval for a separate next stage. A successful synthetic rehearsal can justify asking for an authorized evaluation; it cannot establish safe or effective use on client records. If approvals, integrations, or suitable examples are unavailable, use the time to clarify those limits and mark the trial incomplete. A careful no-go or deferral is informative when it states what was tested, what remains unknown, and what would change the next decision. If results vary sharply by example, preserve that variation in the decision instead of collapsing it into a single average that hides the difficult cases.
Sources: How to run a two-week AI tool trial before you commit; How to Prepare Your Team to Use AI: Two-Week Pilot Plan; AI RMF Playbook: Measure
What does a result justify after two weeks?
At the end of two weeks, decide from the evidence you collected. Continue a limited use only when the task meets its predefined quality standard, review catches material errors, total effort is acceptable, and the data boundary was respected. If a condition fails, the result may still point to a redesign or a question for the approver. It does not justify widening the task or changing information submitted. The National Institute of Standards and Technology's AI Risk Management Framework Playbook recommends documenting test sets, metrics, processes, and materials, and cautions against extrapolating from narrow, non-systematic assessments. Preserve the trial conditions with the result: which task and examples were used, which tool and account settings applied, what counted as a pass, how time was counted, and what the reviewer found. “It worked” cannot tell a later reader whether the workflow, data, or test standard has changed. A rehearsal on independently created synthetic or public inputs earns a narrow conclusion. It can support a request to evaluate the next stage, because the analyst has learned about task mechanics, output structure, and review needs. It cannot establish that client records are safe to submit, that the tool will handle their irregularities, or that the organization has approved such use. The strongest objection is that synthetic examples may be unlike real records and provide no operational evidence. That is right about performance on client data. The rehearsal still has limited value if its conclusion stays confined to prompt design, obvious failure modes, and whether planned checks are workable. A test using organization-cleared material supports a broader, but still bounded, conclusion: the specified task worked or did not work under the tested account, data, and review conditions. It does not authorize another tool, client, data category, or larger workflow. Expansion needs separate approval and monitoring. NIST's AI Risk Management Framework Core calls for defined application scope and documented human oversight; this is risk-management guidance, not proof that a reviewer will catch every mistake. Use three outcomes. Continue the limited approved task if quality, review, effort, and handling pass. Redesign when the tool helps with structure but interpretation should remain manual, or checking erases time saved. Stop or remain in rehearsal when permission is unclear, important errors are hard to detect, or review capacity is inadequate. The Australian National AI Centre's workflow guidance supports clear responsibilities, checks, escalation, and monitoring, but does not establish that this trial improves productivity. Whatever the result, it says nothing by itself about adoption, labor demand, whole-role automation, or job-loss odds.
Sources: AI RMF Playbook: Measure; Redesign your workflow; NIST AI 600-1: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
What is the next action on the next workday?
On the next workday, make a one-page trial card before opening a tool. Name the task; identify the approved tool and account, allowed data categories, and prohibited material. Record the source of truth, output checks, reviewer, time and correction log, stop rule, and decision date. This gives an approver a bounded request to assess. Send unresolved data questions to the person responsible for the account or client information. Do not treat silence, a work login, or a successful demonstration as permission. If approval is unavailable, build an example independently from scratch or use permitted public information. Label results a rehearsal: they can inform task mechanics and review design, but cannot establish that client data may be entered or that a live workflow is ready. The National AI Centre’s “Redesign your workflow” guidance emphasizes clear roles, checks, feedback, and low-cost tests. “How to Prepare Your Team to Use AI: Two-Week Pilot Plan” offers a shared log and review structure. Use both as planning aids, not proof of safety or productivity. Keep the limits with the results, and seek approval before changing the tool, data, task, or scale. To place this task alongside other duties, use the free task checker at /ai-job-risk-checker; its change-pressure signal is not a job-loss probability.
Sources: How to Prepare Your Team to Use AI: Two-Week Pilot Plan; Redesign your workflow
Questions readers ask
Can a synthetic-data rehearsal show that client data is safe to use?
No. It can help test task mechanics, output structure, and review steps on the examples supplied. It cannot establish that client data may be submitted, that performance will transfer to client records, or that a workflow is approved for operational use.
Does a successful two-week trial mean AI can automate the analyst’s job?
No. It can support a bounded conclusion about the tested task, examples, account, and review conditions. It does not establish whole-role automation, broader employer adoption, labor demand, or a probability of job loss.
Sources and notes
- NIST AI 600-1: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
Supports treating privacy risks such as leakage and unauthorized disclosure as a risk category; it does not grant approval or quantify risk for a particular tool or dataset.
- Data access for your managed ChatGPT account
Explains that data access and controls for a managed ChatGPT account can depend on organizational configuration and policy.
- Introduction to anonymisation
Explains that removing direct identifiers may leave information identifiable and that pseudonymized information remains personal data under the UK GDPR framing.
- AI RMF Core
Supports defining and documenting an AI application's scope and human-oversight processes in line with organizational policy.
- AI RMF Playbook: Measure
Supports documenting test sets, metrics, procedures, and materials, and cautions against generalizing from narrow or anecdotal assessments.
- Redesign your workflow
Provides practical guidance on assigning responsibilities, checking accuracy, handling exceptions, and retaining key human decisions.
- How to run a two-week AI tool trial before you commit
Describes a practitioner-recommended two-week trial with a task, baseline, and predetermined decision threshold; it is not independent validation of the duration.
- How to Prepare Your Team to Use AI: Two-Week Pilot Plan
Offers practitioner recommendations for approved accounts, verification checks, logging, and review; it does not establish measured outcomes for this analyst's trial.
Apply this to your own work
See the whole job market at once.
Explore which occupations AI may reshape, then turn the signal into a practical response.
Explore the job map