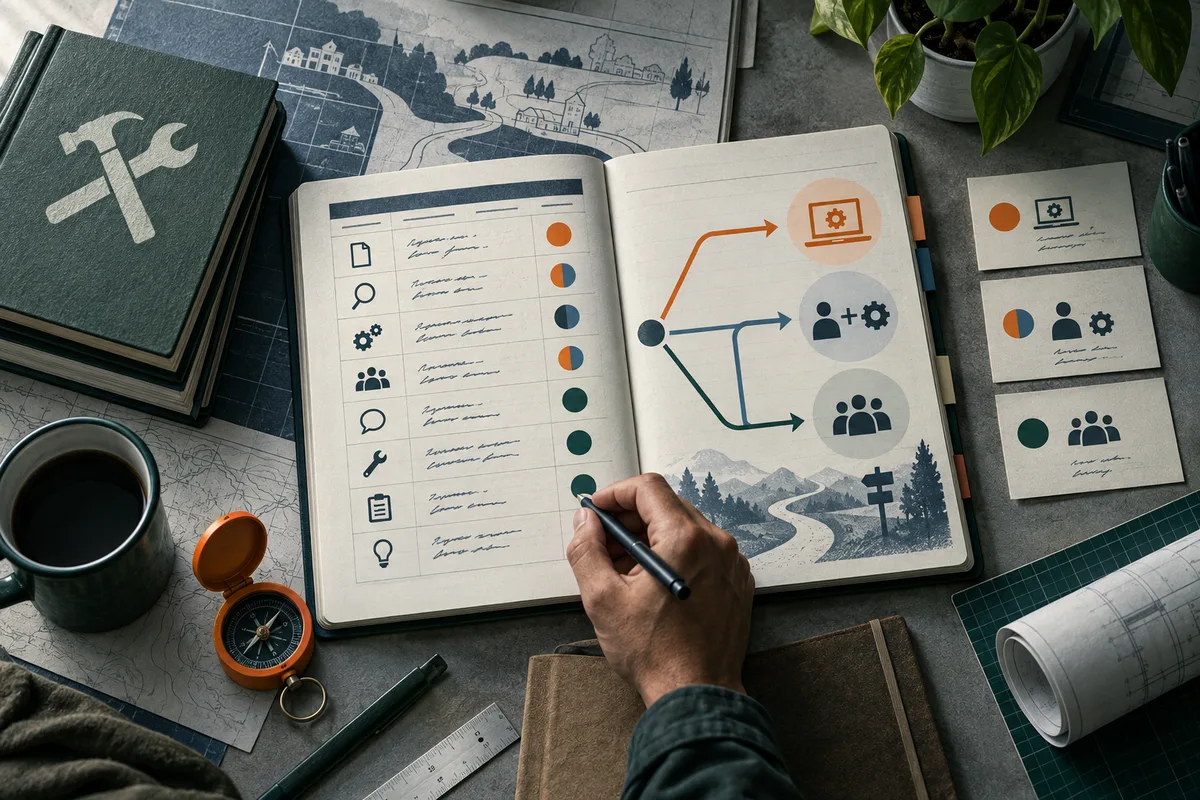
Use the closest O*NET occupation as a checklist, not a forecast. Keep tasks you actually perform, add recurring duties the profile misses, and record possible AI assistance, workplace use, and human review separately. The map helps you identify one task to investigate through an authorized check or workplace conversation; it does not predict whether you or your job will be displaced.
How do I use O*NET tasks to map AI change in my actual job?
Use the closest O*NET occupation as a checklist, not a forecast. Start with your title, inspect its task statements, and keep duties you actually perform. O*NET OnLine Help: Job Duties Custom List describes this title-to-task process and lets users select duties to find occupations with related tasks. Add recurring work the list misses. For each task, note whether AI could assist, whether a tool is actually used for it at your workplace, and what checking, approval, or accountability remains. These are separate questions: a capability match does not establish local adoption, reliable completion, or a staffing decision. The U.S. Bureau of Labor Statistics’ “Artificial Intelligence (AI) exposure categories” states that occupation-level exposure categories do not estimate adoption probability, worker replacement, job loss, or whether AI automates or augments work. Treat your first map as a way to locate uncertainty, not a score of personal risk. Choose one frequent, bounded task to investigate through an authorized small test or a conversation about workflow and review responsibility. Let your goals, income needs, location, time, and other constraints shape what follows. An O*NET match alone does not call for retraining or a career change.
Sources: O*NET OnLine Help: Job Duties Custom List; Artificial Intelligence (AI) exposure categories
What O*NET can and cannot represent
O*NET 31.0 is a periodically updated U.S. occupational information system, useful for giving your work a shared vocabulary and a first list of duties to check. Its O*NET-SOC taxonomy covers work performed in the U.S. economy and defines the occupations for which data is collected, as the O*NET Database page explains. The profile describes an occupational category, not one employee’s exact workflow. A familiar job title may point toward a useful profile, yet titles and duties vary across employers, seniority levels, and hybrid roles. Treat the title as a search clue, then compare listed work with what you repeatedly do.
The database contains occupation-linked task statements, broader work activities, and work context. The O*NET Database page identifies these as distinct data areas, while O*NET OnLine Help: Custom Report explains that tasks are occupation-specific, work activities summarize kinds of tasks across occupations, and work context covers physical and social factors affecting work. Together, these categories help you notice dimensions a title alone can hide. They remain organized around occupations rather than your particular team, systems, handoffs, or priorities.
O*NET reports quarterly database updates, with a primary update in the third quarter, and version 31.0 is the release identified on its resource page. Updates improve the reference but do not make it a live record of every workplace. The Custom Report help page says sample reported job titles are examples supplied by incumbent workers, another reason to compare titles and duties rather than assume a perfect match. Begin with the closest profile; mark tasks that fit, omit those you do not perform, and add recurring duties that are missing. If your role blends occupations, or you work outside U.S. classification coverage, give your own task record more weight than any single profile.
How do I find a useful occupation match?
Start with the occupation title that most nearly describes your work, but do not stop at the title. O*NET OnLine’s “Job Duties Custom List” begins by asking for a current occupation, displays matching occupations, and lets you open one to review its task statements. Select the statements that fit your duties and use the results to find occupations with related tasks. The feature is a way to discover and compare profiles; its matches do not establish that a profile captures your particular job or measure AI exposure. When your title is uncommon, broad, or shared across different kinds of work, search the nearest familiar title first. Read the task list before deciding whether it fits. O*NET’s “Custom Report” help explains that task statements are specific to occupations, while Detailed Work Activities (DWAs) describe activities common across occupations and are less specific than those tasks. In the custom-list results, O*NET calls tasks linked through the same DWA “closely related.” Tasks connected through an Intermediate Work Activity (IWA), a more general activity, appear as less related. These links explain why another occupation may appear in the results: it shares a work activity with a selected task, not necessarily your full role, industry, seniority, tools, or responsibility. A practical comparison needs only two or three plausible profiles. For each, note which recurring duties from your own work are represented, which profile tasks you rarely or never perform, and which duties you perform are missing. Give more weight to repeated, consequential work than to a title that sounds right. If two profiles each describe part of your role, keep the useful task statements from both rather than forcing every duty into one occupational label. O*NET 31.0 documents an occupation taxonomy covering work in the U.S. economy and provides task and work-activity data; it is a structured reference, not an individualized description of every employer’s job design. For example, a role that combines preparing routine updates with coordinating exceptions may resemble different occupation profiles in different parts of the week. That comparison can help name the work more accurately. It cannot tell you whether a tool can perform those tasks reliably, whether your workplace uses one, or whether a related occupation is a sensible move. Task similarity is about the organization of work in the taxonomy; AI capability and workplace use require separate evidence. Treat the resulting shortlist as a better starting inventory for your own task map, not a score or a verdict about your job.
Sources: O*NET OnLine Help: Job Duties Custom List; O*NET OnLine Help: Custom Report; O*NET Database
How should I read O*NET's task ratings?
Read each O*NET task rating as an occupational description with a specific denominator, not as a measurement of your own workweek. “O*NET OnLine Help: Scales, Ratings, and Standardized Scores” defines relevance as the percentage of job incumbents who rated a listed task relevant. It tells you how broadly a task applies in the occupation. It does not say how many hours you spend on it or whether AI performs it. Frequency answers another question: how often incumbents report that a task occurs within a given period. O*NET groups reports into “frequently,” “occasionally,” and “rarely.” Frequently includes daily, several times a day, hourly, or more; occasionally includes more than once a month and more than once a week; rarely includes once a year or less and more than once a year. These categories distinguish recurring duties from infrequent ones, but do not give an individual a precise time share. “Frequently” does not mean “takes most of my day”: a brief task can recur many times, while a long task may happen less often. Importance is separate. O*NET rates task importance from 1, “not important,” to 5, “extremely important.” A task may matter greatly when it occurs without being frequent; another may recur often but be less consequential. Keep relevance, frequency, and importance in separate fields because they describe different aspects of work. The “core” label is an occupational threshold, not a personal verdict. O*NET identifies core tasks using relevance of at least 67 percent and mean importance of at least 3.0. Supplemental tasks fall below one or both thresholds. This organizes the task list; it does not establish that every worker performs every core task or that a supplemental task is unimportant in your role. Standardized scores need care. O*NET converts some underlying scales to a 0–100 display. Its help page gives an importance rating of 3 on the 1–5 scale as a standardized score of 50. That 50 is not 50 percent of a workday, a likelihood of AI use, or an exposure score. The O*NET database page describes task statements and ratings as occupation-linked data, not an individualized time diary. For your map, retain O*NET ratings as reference fields, then record your own observed frequency and approximate time separately over a representative stretch of work. Do not add or multiply population ratings into a personal “AI risk” number: that combines distinct measures and leaves out task sequence, review effort, exceptions, and consequences. Compare the occupation profile with your actual work and note where they differ.
Sources: O*NET OnLine Help: Scales, Ratings, and Standardized Scores; O*NET Database
How do I catch duties the profile misses?
Build a short record of recurring work from a representative stretch of normal work, then compare it with the closest O*NET profile. Add duties the occupation list does not make visible: preparation, review, coordination, exceptions, approvals, and communication. A profile is a structured starting inventory, not a complete description of every position. O*NET 31.0 describes work and worker characteristics for occupations in the U.S. economy and is updated quarterly, according to the O*NET Database page; that breadth supports comparison, while the local details still need your correction. For each recurring duty, write an action, its object, and the outcome: for example, “reconcile source figures to produce a weekly status summary.” Then note how often it occurs, roughly how much time it takes, what triggers it, what information it uses, and who receives or depends on the result. Record handoffs, exceptions, review steps, approvals, and what an error could affect. Keep estimates approximate and mark unknowns. The goal is a legible sequence of work, not a precise personal score. Imagine a role that prepares a weekly status summary. “Draft summary” might cover arranging routine updates into a readable document. The actual work could also involve reconciling figures that conflict across sources, explaining an exception, confirming which source is authoritative, and obtaining sign-off before circulation. Record those as distinct duties when they recur. Otherwise, the map may miss the checking and coordination behind a reliable summary. This is an illustration of task decomposition, not a claim about employer AI use. Use O*NET Emerging Tasks as prompts for duties worth checking, not as evidence that a new duty is common in your workplace. The O*NET 31.0 Data Dictionary describes these entries as new or revised task statements proposed for future data collection. It says statements may be developed from sources including feedback from surveyed incumbents, research into emerging technologies, and professional-association information. That provenance makes an entry a useful question to take back to your own work record; it does not establish prevalence, adoption, or a change in staffing. A missing item may reflect an occupation-level description or hybrid position, not a genuinely new duty. The resulting worker-corrected list can support a focused conversation: “These are the duties I handle repeatedly; which are changing, and who reviews the output?” Keep an uncertainty note beside duties whose frequency, ownership, or future status you cannot verify. This keeps the map useful while giving the discussion a concrete work sequence to examine.
Sources: O*NET 31.0 Emerging Tasks; O*NET Database
What should I separate in the task map?
For each task, keep three questions in separate columns: what current AI tools might assist with, what people in this workplace actually use, and what human review or responsibility remains. A capability match is a reason to investigate exposure. It is not evidence that a tool is deployed here, can complete the whole process reliably, or will remove a role. The U.S. Bureau of Labor Statistics makes this boundary explicit in “Artificial Intelligence (AI) exposure categories”: theoretical measures concern possible assistance or completion, while observed-use measures map interactions to occupational tasks. Neither establishes whether workers in a particular occupation use AI on the job, and the categories do not estimate adoption probability, job loss, or worker replacement. Make the task small enough to inspect. Record input, expected output, handoffs, authorization, exceptions, checking time, error consequences, downstream reliance, and approval. “Write a summary” may be too broad: finding records, resolving conflicting dates, explaining an exception, and signing off can have different requirements despite producing one document. The ILO’s “Generative AI and Jobs: A Refined Global Index of Occupational Exposure” combines task data, expert input, and model predictions for occupational comparison; it does not observe this employer’s workflow. Consider an illustrative ledger row: “draft a first-pass weekly status summary from approved project updates.” Possible assistance: organize supplied text into a draft. Workplace use: unknown until someone confirms whether an approved tool is used for these inputs. Remaining work: check statements against source updates, resolve conflicts, remove information not cleared for sharing, and obtain sign-off. Verification time and error consequences remain unknown until established. A polished draft alone does not show whether the complete task is faster, accurate enough, or safe to delegate. Bottlenecks and complements matter. If source reconciliation or approval governs completion, easier drafting may change one step while leaving the overall process dependent on human judgment. A repeatable, checkable draft could instead free time for another duty; whether that happens is a workplace question, not an inference from capability. BLS notes that its input measures treat occupations as bundles of independent characteristics and do not account for bottlenecks or complementarities, cautioning against one exposure label. Mark each entry as documented capability, observed local use, confirmed review rule, or unknown. NIST's “Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile” offers guidance relevant to output evaluation, privacy, and oversight; it does not prove a specific workflow is safe. Unknowns point to a bounded check or conversation, not a staffing forecast or individual displacement prediction.
Sources: Artificial Intelligence (AI) exposure categories; Generative AI and Jobs: A Refined Global Index of Occupational Exposure; Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
What exposure research adds—and what it cannot add
Exposure research answers a bounded question: how do analysts compare the kinds of work AI might assist or perform? It does not describe your employer’s plans. The U.S. Bureau of Labor Statistics’ “Artificial Intelligence (AI) exposure categories” combines five external measures for 831 detailed occupations: three theoretical capability measures and two based on observed AI interactions mapped to occupational tasks or activities. BLS converts scores to within-source percentile ranks, combines theoretical and observed dimensions separately, then groups occupations into four relative categories. Of 4,155 possible occupation-source values, 211 were imputed, affecting 75 occupations. This is comparison across occupations, not direct observation of workplace use.
BLS says the categories do not estimate adoption probability, productivity, wages, employment change, or worker replacement, and do not distinguish automation from augmentation. Inputs have different definitions, rely on occupational crosswalks and imputation, and include theoretical capability assumptions no later than mid-2023. BLS notes that occupations are treated as bundles of independent characteristics, leaving bottlenecks and complementarities out. A relative category can prompt questions about your profile; it cannot show whether your organization approved a tool, whether its output survives checking, or whether review changes the process.
The International Labour Organization’s 2025 working paper, “Generative AI and Jobs: A Refined Global Index of Occupational Exposure,” uses a different method. Researchers sampled from 29,753 tasks in Poland’s occupational classification and surveyed 1,640 employed people across ISCO-08 major groups. Their survey collected perceptions of automation potential for 2,861 tasks. Researchers compared those inputs with international expert surveys and Delphi-style discussions, then used the task repository to predict scores for ISCO-08 documentation. This is a global occupational framework, not a measure of adoption at one employer. Its conclusion that job transformation is the most likely impact is the paper’s interpretation, grounded in its finding that most occupations contain tasks requiring human input, not an individual forecast.
Use both studies as context around, not validation of, your task map. Ask separately: could AI assist this task; is an approved tool used here, and what review does it require; and what evidence bears on demand or staffing? Your inventory and a bounded workplace check can inform the first two at different scales. Demand requires separate labor evidence. Displacement also depends on decisions these exposure methods do not measure. Keep the answers distinct and uncertainty visible.
Sources: Artificial Intelligence (AI) exposure categories; Generative AI and Jobs: A Refined Global Index of Occupational Exposure
Which tasks are plausible candidates for a bounded check?
A sensible first candidate is a recurring digital task with authorized inputs, a stated output standard, and a reviewer able to catch consequential errors. High exposure alone does not make a task suitable. Ask instead: can this step be assisted in a contained way, and can the result be checked? Screen the task against seven conditions. Are inputs reasonably stable, and is the output bounded, such as a draft summary rather than an open-ended judgment? Can you discard or reverse the result? Can someone with enough context check it? Are the data and tool approved for this use? A privacy or safety constraint can rule out a test regardless of other answers. For example, drafting an internal outline from approved, non-sensitive material may be easier to review than preparing a client-facing explanation from a confidential record. A polished draft does not prove its claims are supported. Where a statement could affect a decision, the reviewer needs source material and authority to reject or correct it. Verification time matters too: if checking takes longer than the task saves, the workflow may not improve. The National Institute of Standards and Technology's *Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile* is voluntary organizational guidance. It organizes suggested actions for identifying, evaluating, and managing generative AI risks; it does not certify a workplace tool or choose a task for an individual. Apply its risk-management lens to the use case, then follow employer approval and data-handling rules. The Bureau of Labor Statistics' *Artificial Intelligence (AI) exposure categories* cannot select a trial either. BLS says its relative occupational categories do not measure adoption probability, productivity, job loss, or whether work is automated rather than augmented. Local authorization and checkability govern a test. If a task clears those conditions, agree with the responsible manager on a narrow comparison. Apply the same acceptance criteria to the current process and an approved assisted version; record elapsed time, correction effort, and whether each output meets the standard. Stop if permission, quality, or accountability is unclear. This can inform further workflow review, not establish wider adoption or future staffing. Bring one task and its unresolved risk to a supervisor, and ask who would verify each output before a trial begins.
Sources: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile; Artificial Intelligence (AI) exposure categories
How do I compare the map with other evidence?
The O*NET profile, your corrected task record, and a local workflow check answer different questions. Keep them side by side: the profile offers standardized coverage, your record shows what you do, and an authorized trial or informed conversation can reveal how one process works here. None alone establishes whether a role will shrink. Their different units and blind spots make comparison useful.
O*NET OnLine Help: Job Duties Custom List describes starting with an occupation title, selecting relevant task statements, then finding occupations connected through shared Detailed or Intermediate Work Activities. This provides common vocabulary and can surface duties missed by a title search. Its unit is an occupation, not your personal workload. A hybrid position or employer-specific process may fit several profiles imperfectly. Mark gaps rather than forcing every duty into one title.
Your corrected record changes the unit to your recurring work: what arrives, what you produce, how often, who reviews it, and what happens when it is wrong. It can reveal duties absent from the profile and show which occupy your week. Memory or a short observation period may miss seasonal work or rare but consequential exceptions, so label estimates and revise them when better evidence appears. The record describes your work locally; it does not establish reliable AI performance or employer use.
A permitted, bounded trial or an informed conversation adds narrow workplace evidence: whether a tool is available and authorized, where output needs correction, and who remains responsible. One trial cannot establish department-wide adoption, future staffing, or market change. The BLS page Artificial Intelligence (AI) Exposure Categories explains that its relative occupational categories combine theoretical measures and observed AI interactions mapped to work, but do not directly observe whether workers in a particular occupation used AI on the job. BLS says exposure is not an adoption probability, employment forecast, or worker-replacement estimate. Treat it as context, not a local workflow verdict.
Keep labor demand separate if considering a move. BLS Occupational Employment Projections Data provides U.S. occupation-level employment, openings, wage, and projection information; it does not describe your locality, qualifications, or likely outcome. Current postings show employer requests at that moment, not durable demand or personal fit. Outside the United States, consult a national or regional labor source and account for its geography.
The practical order is profile, corrected record, then local check, with demand evidence added when considering a move. If the O*NET match is poor, let documented duties lead and use the profile as a vocabulary aid. Ask which recurring task you can investigate safely, and who can confirm its review and responsibility.
Sources: O*NET OnLine Help: Job Duties Custom List; Artificial Intelligence (AI) exposure categories; Occupational Employment Projections Data
How do I choose a next move without turning the map into a forecast?
Choose the next step by identifying what your map cannot tell you. If you do not know whether a recurring task can be assisted safely, and workplace rules allow it, propose a supervised check with authorized inputs, a clear quality standard, and a reviewer. If the unknown is local use, ask a manager how the workflow is changing, who checks outputs, and whether responsibilities are shifting. A task map prompts evidence gathering; it does not by itself justify quitting, retraining, or assuming a role will disappear. Keep labor demand separate. The U.S. Bureau of Labor Statistics’ Occupational Employment Projections Data provides estimates of employment change, openings, education, training, and wages by occupation. These are projections, not one worker’s outcome or a local guarantee. Job postings show what employers request now, but are snapshots, not proof that a skill will secure a job. Outside the United States, use local labor information; O*NET categories may fit less well. Before a larger move, compare upgrading your current role, moving adjacent using existing experience, and broader retraining. Check each against your goal, salary floor, location, learning time and cost, and health. A bounded trial or conversation may answer one unknown. Bring your task map to a manager and ask: which task is changing first, and who will verify its output? If local evidence changes your assumptions about the work, accountability, or demand, revise the map.
Questions readers ask
Does an O*NET task rating show how much of my workweek AI could affect?
No. O*NET ratings describe tasks reported by incumbents in an occupation; they do not measure your personal hours or predict AI use or job loss. Record your own frequency and approximate time separately.
Sources and notes
- O*NET OnLine Help: Job Duties Custom List
Explains selecting occupation tasks and finding occupations linked through shared work activities.
- Artificial Intelligence (AI) exposure categories
Describes relative occupational exposure categories and states they do not estimate adoption probability, job loss, or worker replacement.
- O*NET Database
Identifies O*NET 31.0, its U.S. occupational scope, task data, and quarterly update cadence.
- O*NET OnLine Help: Custom Report
Distinguishes occupation-specific tasks from broader work activities and work context.
- O*NET OnLine Help: Scales, Ratings, and Standardized Scores
Defines task relevance, frequency, importance, core-task thresholds, and standardized rating scales.
- O*NET 31.0 Emerging Tasks
Defines Emerging Tasks as new or revised statements proposed for future data collection.
- Generative AI and Jobs: A Refined Global Index of Occupational Exposure
Describes the ILO's task-based global exposure method, including task data, worker perceptions, expert input, and model predictions.
- Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
Provides voluntary generative-AI risk guidance relevant to evaluation, privacy, and human oversight.
- Occupational Employment Projections Data
Provides U.S. occupation-level projection, employment, openings, education, training, and wage data.
Apply this to your own work
See the whole job market at once.
Explore which occupations AI may reshape, then turn the signal into a practical response.
Explore the job map