Current AI can help with bounded tasks such as summarizing supplied material, drafting routine text, and sorting information. A useful first pass does not prove a dependable workflow: reliability depends on visible context, checkable results, error costs, reversibility, and accountable review. Test one low-risk recurring task, counting verification and rework as well as first-pass speed.
What can current AI do at work, and what can it not do reliably?
Current AI can produce useful first passes when a task has clear inputs and a defined output: summarize supplied material, draft routine text, sort information, or suggest a next step. That shows capability on a task, not that a whole workflow can run without review. Reliability is harder to establish when context is missing, answers are difficult to check, errors carry serious consequences, or someone must own the decision. NIST’s Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile describes confabulation as confidently stated false or erroneous content. Fluent wording is not proof of correctness. For work decisions, use a simple reliability ladder: a plausible output; a supervised contribution that someone checks and corrects; and a dependable workflow result that meets its criteria consistently. This ladder is an editorial synthesis, not a standardized score. The research summarized here was accessed October 7, 2026; capabilities can change, and findings do not transfer automatically across tools or workplaces. Before asking whether AI can do your job, name one recurring task, define a correct result, and identify who checks and owns it. Test a low-risk example, counting review and rework as well as first-pass speed.
Sources: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
What does ‘can do’ mean when the unit is a task?
A system can generate, classify, summarize, extract, transform, or suggest from supplied information. That establishes capability for a defined operation. Reliable work requires a clear outcome, an acceptable quality threshold, and a way to check it. A convincing answer to one prompt shows a possible output, not that a workflow can depend on it. Work also includes exceptions, approvals, and responsibility. Keep five ideas separate. Capability is what a system can perform under specified conditions. Exposure is whether it could assist or complete tasks in a role. Observed use records AI interactions in a dataset. Adoption means an organization has put a system into its practices. Displacement concerns changes in jobs or workers. Evidence for one does not establish the next: an exposed task may not be used or adopted, and neither fact establishes job loss. The International Labour Organization’s *Generative AI and Jobs: A 2025 Update* assesses nearly 30,000 tasks across occupations using task data, expert input, and AI predictions. It assigns exposure gradients based on task scores and variability. The brief estimates one in four workers globally is in an occupation with some exposure, while emphasizing continued human input and that most jobs are more likely to transform than become redundant. This is potential occupational exposure, not an individual job-loss estimate. A task is more useful than an occupation label because a job bundles operations. Imagine a project-coordinator ledger: meeting notes might be summarized, dates extracted from supplied files, and a status update drafted. Resolving conflicting schedules or getting approval before changing a commitment has different inputs and consequences. AI might prepare a summary, while completion depends on authoritative records and a person empowered to resolve ambiguity. This is an illustration, not measured evidence about coordinators or a particular system. The U.S. Bureau of Labor Statistics’ *Artificial Intelligence (AI) Exposure Categories* defines theoretical exposure as AI’s potential to assist with or complete occupational work. For its 2025–35 projections, BLS combines five sources: three theoretical measures and two observed-use measures mapped to tasks or work activities. Categories compare occupations relatively. BLS says they do not measure job loss, productivity gains, automation probability, wage effects, or adoption probability; observed-use measures do not directly show workers in an occupation used AI on the job. BLS notes its sources treat occupations as bundles of independent tasks and do not account for bottlenecks or dependencies. A result may be easy to generate but hard to verify without another person, permission, or missing context. A human-led task may also contain a small step AI could assist with. An occupation’s category cannot tell a worker which duties to delegate or whether the full workflow will change. For your decision, list recurring tasks and note required information, what a correct result looks like, who checks it, error cost, and whether it can be reversed. A draft a knowledgeable person can compare with records may be worth evaluating. A commitment based on facts the system cannot see is different: plausible wording is not reliable completion. Exposure measures point to tasks to inspect; inputs and accountability determine what “can do” means.
Sources: Generative AI and Jobs: A 2025 Update; Artificial Intelligence (AI) Exposure Categories
What current AI handles well when the work is bounded
AI is most useful when a task has a clear boundary: relevant source material is available, the requested output is specified, examples show acceptable work, and someone can check the result against a trusted record or rule. Under those conditions, it can produce a first pass, transform information, or suggest options for a person to verify. That is a contribution, not proof the system can own a workflow. Extracting fields from a form is easier to check than deciding what to do with incomplete records. Bounded task classes include extracting dates and amounts from documents, summarizing a supplied transcript, reformatting notes into a standard template, drafting routine text from an approved brief, sorting items by defined categories, and suggesting code changes against a stated requirement. Each has visible inputs and an output that can be compared with something: the source, template, rule, test, or reviewer’s criteria. Checking still takes work: a summary can omit a qualification, a draft misstate the brief, or suggested code pass one test and break another. The question is not whether a system emits the requested form, but whether the result meets the task’s quality threshold after review. METR’s “Task-Completion Time Horizons of Frontier AI Models” shows why task boundaries matter in capability evaluations. Its May 2026 page fits success curves to more than a hundred software tasks, estimating human expert completion time and reporting durations associated with predicted 50% and 80% success. The tasks are mainly in software engineering, machine learning, and cybersecurity; they are self-contained, well-specified, and have criteria that can be evaluated automatically. This makes completion legible to a benchmark, but does not establish reliable performance on a similarly long workplace assignment with tacit knowledge, changing requirements, or coordination. METR notes that its tasks have less context than professionals’ daily work and that measurements above 16 hours are unreliable with the current suite. The lesson concerns measurable task conditions, not job capability. Workplace studies also show that gains can differ by worker and setting. “Generative AI at Work” studied 5,172 customer-support agents during a staggered assistant rollout. Access to the assistant raised issues resolved per hour by 15% on average, but effects varied: less experienced and lower-skilled agents improved both speed and quality, while the most experienced and highest-skilled agents had small speed gains and small quality declines. The authors report the largest gains for relatively rare problems, where workers had less baseline training. This is one setting, not a forecast for other occupations. Guidance may help where practice is limited; experienced workers may gain less or need to correct mismatched suggestions. In “How much does AI impact development speed? An enterprise-based randomized controlled trial,” 96 full-time Google software engineers used internal AI features on a complex enterprise task. The trial reports shorter time on task, with a best estimate of about 21%, but a large confidence interval. Its authors caution that results from one organization, task, and summer 2024 tool suite may not carry across tools or over time. This supports a bounded conclusion: assistance can speed specified work in particular settings, but neither result establishes dependable performance across a professional’s duties. For a first workplace test, choose a frequent, low-risk task with approved inputs and a checkable output, such as converting public meeting notes into a standard action-item format where policy allows. Compare the usual process with an assisted pass. Record accuracy, corrections, and total time including review and rework. Include an ordinary case and a less tidy one; a clean example alone can hide limits. If quality holds and total effort falls, cautious use may make sense. If review consumes the time saved or errors are hard to detect, keep the task human-led or narrow the system’s role. Evidence supports testing bounded assistance; fast output alone is not completed work.
Sources: Task-Completion Time Horizons of Frontier AI Models; Generative AI at Work; How much does AI impact development speed? An enterprise-based randomized controlled trial
Why does reliability break when context, novelty, or consequences matter?
Reliability breaks when an answer depends on facts the system cannot see, conditions that are changing, or a decision whose quality is difficult to check. A polished response shows that the system produced fluent language; it does not establish that its facts are complete or correct. The National Institute of Standards and Technology’s *Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile* calls confidently presented erroneous content “confabulation.” It notes that outputs can diverge from a prompt or contradict earlier statements, particularly in open-ended or context-heavy work. NIST describes a risk mechanism, not a failure rate for any specific tool or task. Some failures begin before reasoning. If a request omits a current policy, a customer’s latest message, or the purpose behind a rule, the model cannot account for that information unless it is available through an appropriate source. This is a visibility problem. More material may help, but cannot guarantee it will notice details or resolve contradictions. Other failures arise even when inputs are present: it may omit a constraint, merge distinct cases, or state an unsupported answer confidently. Treating every mistake as a prompt problem is misleading. For changing facts, a current source of truth and a way to check the result matter more than a longer instruction alone. Novel cases are harder to judge when no familiar pattern or example exists. Requirements can conflict: a response may need to be concise but complete, follow a standard while handling an exception, or satisfy a customer without promising what policy forbids. A reviewer may recognize trade-offs through organizational knowledge. AI may help organize options or draft questions, but someone with relevant authority and context must own the interpretation. AI can contribute, but preparing a decision and owning it differ. Long chains create another failure path. Each step can introduce an error that later steps treat as correct. Without checks between steps, an early omission can reach a polished final result. METR’s task-completion time-horizon page estimates success on a software-heavy suite of self-contained tasks with clear success criteria. It says measurements above 16 hours are unreliable with its current suite. This tests sustained work on defined tasks, not long workplace workflows with hidden context, handoffs, or ambiguous criteria. Results apply to tested tasks. The consequence should shape the control. A draft that is easy to compare with a source and revise differs from an inaccurate customer commitment, missed legal deadline, or action affecting access to a service. AI may still prepare a summary while a qualified person checks evidence and approves. Describing a physical action is also different from safely performing it in a changing environment. These distinctions do not rule out assistance; they show why verification, permission, and responsibility belong in the workflow. When context, exceptions, or consequences matter, set four controls: identify the approved source of truth; route unfamiliar or conflicting cases to a person; check consequential claims against independent records or a suitable rule; and name who owns the final decision. Strengthen checks when errors are harder to reverse or more harmful. If an output cannot be checked affordably, its source is incomplete, or no one can accept responsibility, keep the task human-led or limit AI to preparation. The question is not whether an answer sounds right, but whether the workflow can detect and contain a wrong one.
Sources: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile; Task-Completion Time Horizons of Frontier AI Models
How should you compare a draft, an assistant, and a dependable workflow?
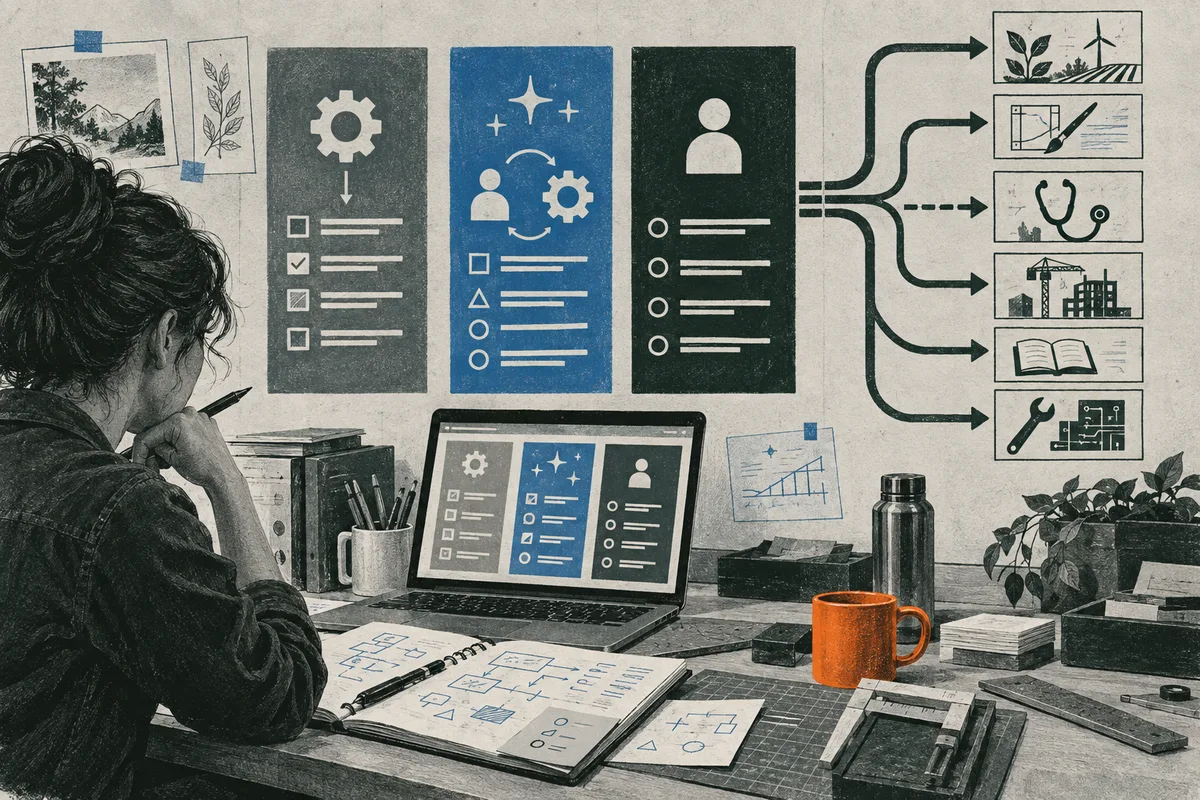
A fair comparison asks whether the same task and inputs are completed better with AI. Do not compare a polished model answer with an entire worker’s job. Compare the baseline workflow with an AI-assisted workflow from start to accepted result: time to prepare inputs, generate or revise output, check it, correct errors, handle exceptions, and obtain approval. Record quality, error severity, and who owns the final decision. Three modes are easy to confuse. In automation, a person delegates a task and receives an output with little interaction. In augmentation, the person and system iterate: the system proposes, the worker supplies missing context, checks, edits, or redirects. A dependable workflow is a higher bar than either label. It includes reliable inputs, defined acceptance criteria, a way to catch errors, an exception route, and an accountable owner. The labels describe how work is done, not whether it is dependable or widely adopted. Use four questions to choose a mode. Is context visible in approved inputs, or does success depend on inaccessible history or tacit rules? Can a reviewer check against records, a rubric, or a test? What would an error cost, can it be reversed, and who has authority to approve the outcome? They locate a sensible boundary; they are not a score. | Conditions | Starting comparison | | --- | --- | | Visible context, checkable output, low cost and reversible | Compare a supervised first pass with baseline; automate only after checks work. | | Judgment needed or errors costly | Compare an assistant’s options or draft with human review and decision. | | Context missing, checks weak, or harm hard to reverse | Keep the decision human-led; limit AI to bounded preparation. | These are starting points, not universal rules. A low-risk output can become consequential when it is sent externally, copied into many records, or used as the basis for another decision. Conversely, a high-stakes workflow may still use AI for a narrow clerical step if the original record remains authoritative and every result receives an effective check. The evidence shows why the comparison must stay local. In “Generative AI at Work,” a study of 5,172 customer-support agents used a staggered introduction of an AI assistant and reported a 15% average increase in issues resolved per hour. Less-experienced and lower-skilled agents improved speed and quality; the most experienced and highest-skilled had small speed gains and small quality declines. That is evidence about one assistant in one support setting, not a general estimate for knowledge work or a guarantee that an individual workflow will improve. “Using AI in the Workplace” reports that four in five workers in the OECD surveys said AI improved their performance, while three in five said it increased enjoyment of work. Those are workers’ reported experiences, not a controlled measurement of output quality or time saved. That report does not establish task accuracy, net time saved, or suitability for delegation. Anthropic’s “Economic Index: New Building Blocks for Understanding AI Use” analyzes samples of one million Claude.ai conversations and one million first-party API transcripts. It distinguishes automation from augmentation and adjusts task coverage for estimated success, while noting users select expected-to-work tasks and may split complex work into steps. This is a provider’s sample of platform activity, not a representative census of employers or an independent causal estimate. The sources therefore support matched, end-to-end task comparisons, not general productivity or job-security claims.
Sources: Economic Index: New Building Blocks for Understanding AI Use; Using AI in the Workplace; Generative AI at Work
What does the evidence say about capability, adoption, and job change?
The evidence supports two conclusions at once: current AI can perform useful work in selected tasks, and that capability does not tell us how much an employer will adopt, whether a whole workflow will improve, or whether a particular worker will lose a job. These are separate steps. A capability study asks whether a system can complete a defined task; exposure analysis asks whether tasks in an occupation appear compatible with that capability; observed-use data records where people use particular systems. Adoption depends on organizational choices, while labor-market effects depend on what happens after work is redesigned. Treating these links as interchangeable turns a signal into a prediction it cannot support. The International Labour Organization’s 2025 global index measures potential exposure, not jobs already changed. It combined assessments of nearly 30,000 occupational tasks with expert validation, AI-assisted scoring, and harmonized labor data. The ILO reports that one quarter of global employment is in occupations with some potential generative-AI exposure, while describing transformation as more likely than full replacement. Clerical work ranks highly, and exposure also reaches some digitized cognitive occupations. These findings indicate where closer task analysis may help, not whether systems are available, reliable, adopted, or able to complete every duty. The ILO says constraints and skills gaps make implementation vary by country and sector. The U.S. Bureau of Labor Statistics makes the boundary explicit in its AI exposure categories for the 2025–35 projections. BLS combines five external sources: three theoretical measures of how capabilities match work, and two measures mapping observed system usage to occupational tasks or activities. The result is relative across occupations, not an absolute measure of AI use; observed-use inputs do not establish that workers in an occupation used AI on the job. BLS cautions that exposure is not a forecast of job loss, productivity, wages, or adoption probability; its categories also do not distinguish automation from augmentation. Some theoretical inputs describe capabilities only through mid-2023, and task-bundle methods miss bottlenecks. Even a combined indicator is a prompt for investigation, not a verdict. Capability benchmarks answer a narrower question. METR’s task-completion horizon estimates performance on a software-heavy set of self-contained tasks with clear criteria. It can show progress on those tasks, not dependable performance across work or tasks relying on tacit context. Platform usage likewise shows sampled users brought tasks to a system, not broad access, employer integration, or replacement of paid hours. Anthropic’s January 2026 Economic Index illustrates the difference, with a provider-data limitation. It analyzes random samples of one million Claude.ai conversations and one million first-party API transcripts, principally from November 2025, and considers task success as well as coverage. Across pooled reports, Claude appeared in at least a quarter of tasks for 49% of jobs in its sample. Yet its adjusted measure changes which occupations appear most affected once estimated task success and time spent are considered. It says mapping its service tasks to real-world job change remains uncertain. This is one provider’s sample, not all workers; its productivity extrapolations are not causal estimates of economy-wide gains. Together, the sources show real capability and uneven use, while leaving adoption and displacement unresolved. Demonstration-to-adoption depends on data access, privacy, integration costs, quality checks, exceptions, management, demand, and whether saved time expands output or reduces staffing. The evidence supplies no universal conversion rate. For a worker, high exposure should prompt a task-level check and a look for actual workplace signals, such as approved tools, changed procedures, new review duties, or altered demand. It is not, by itself, a reason to quit or retrain; low exposure is no guarantee of safety. A score identifies questions, not the decision.
Sources: One in four jobs at risk of being transformed by GenAI, new ILO–NASK global index shows; Artificial Intelligence (AI) Exposure Categories; Economic Index: New Building Blocks for Understanding AI Use
Which parts of your own workflow should you test first?
Start with a recurring task that has a narrow output, approved inputs, and a reviewer who can check it without spending more time than the task itself. Choose work where an error can be caught before it reaches a customer or decision. The test is not whether a tool “works” in general; it is whether assistance improves this task under ordinary conditions. Describe the task observably. “Prepare a weekly status summary from approved project updates” is testable; “help with project management” is not. Specify required content, authoritative records, and failure conditions. For example, dates, owners, and blockers should match source updates, and contradictions should be surfaced rather than silently resolved. Review then concerns evidence and requirements, not polished wording. Set a baseline first. On a normal case, record time spent gathering inputs, producing the result, checking it, and correcting it. Choose a quality measure tied to the task, such as missing fields, mismatches against source records, or rubric items met. One attempt is only a starting reference; if practical, compare several representative cases, including differences in difficulty. Give the assisted version comparable inputs and the same review standard. Check workplace policy and data permissions before using a tool. Use only approved services and material you are allowed to share. If the task involves private customer details or confidential plans, do not paste them into an unapproved service for a trial. NIST’s *Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile* identifies data privacy and accountability as risks to manage in use. Permission is part of suitability, not an afterthought. Try ordinary cases and a few edge cases: a missing field, conflicting updates, unfamiliar format, or request outside the rules. Check every material claim against source records or an agreed rubric. NIST describes confabulation as confidently presented erroneous content, including output that diverges from a prompt or input. A fluent summary might still omit a blocker. Keep source records available, expose uncertainty, and verify rather than infer from tone. Log total effort on both sides: setup, interaction, review, corrections, escalation, and rework. Record error type and severity, including whether it was caught before use. The OECD’s *Using AI in the Workplace* reports that four in five surveyed workers said AI improved performance and three in five said it improved enjoyment. These are self-reports, not controlled estimates for your task or proof that review costs vanish. They show that workers can report benefits; your comparison must establish whether this workflow benefits. Decide in advance when to stop. A serious error, repeated unsupported detail, improper data exposure, or review effort that erases time saved is reason to pause, narrow the task, or return to baseline. If representative cases meet the quality bar and total effort falls, expand only to a nearby task with similar inputs and consequences. Keep a person responsible for exceptions and final use. This bounded check is not a scientific trial, nor evidence about employer adoption or how a role will change. It answers a smaller practical question: where does assistance help, what must still be checked, and what does checking cost? If no low-risk task is available or policy is unclear, resolve that constraint before testing.
Sources: Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile; Using AI in the Workplace
What is the next proportionate move?
Make one reversible, low-risk workflow test before making a large career decision. A high task-exposure signal is a reason to inspect change, not a personal forecast. The U.S. Bureau of Labor Statistics’ AI Exposure Categories separates theoretical exposure from observed use and cautions that exposure alone does not establish job loss, productivity gains, automation probability, or wages. The International Labour Organization’s Generative AI and Jobs: 2025 Update estimates potential task exposure in occupations; its global figures do not tell an individual what will happen at a particular employer. Adoption, task redesign, labor demand, and displacement remain separate questions.
List recurring tasks . Pick one frequent task with approved inputs, a clear quality check, and a mistake that can be caught and reversed. Check workplace policy before entering information into a tool. Record normal completion time and the quality standard. Compare an AI-assisted attempt with that baseline, including review, corrections, and rework. Measure the completed task, not a fluent first draft. Stop or narrow the trial if an important error escapes the check or review removes the benefit.
Use the result to choose a proportionate next step. If checking remains manageable, build verification or domain knowledge to supervise the tool, then consider another bounded task. If it does not help, examine whether missing context, poor integration, or task fit explains why before investing in retraining. A larger move requires separate evidence about role changes, demand, and your constraints. The free task-level checker at /ai-job-risk-checker organizes change-pressure signals and first actions; it does not calculate a validated probability of displacement. Reliability and workflow integration, not fluent output alone, determine whether a capability changes your work.
Sources: Artificial Intelligence (AI) Exposure Categories; Generative AI and Jobs: A 2025 Update
Sources and notes
- Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
Defines confabulation and describes risks including confidently presented erroneous content.
- Generative AI and Jobs: A 2025 Update
Supports the global task-exposure estimate and the distinction between exposure and job loss.
- Artificial Intelligence (AI) Exposure Categories
Explains BLS exposure categories and their limits as measures of job loss or adoption.
- Task-Completion Time Horizons of Frontier AI Models
Describes METR's software-heavy benchmark and the limits on transferring results to ordinary work.
- Generative AI at Work
Reports a customer-support field study's average productivity result and variation by worker experience.
- How much does AI impact development speed? An enterprise-based randomized controlled trial
Reports a software-engineering trial result and cautions against generalizing beyond its setting.
- Economic Index: New Building Blocks for Understanding AI Use
Analyzes sampled platform conversations and distinguishes task coverage from estimated successful task completion.
- Using AI in the Workplace
Reports workers' self-described performance and enjoyment while distinguishing survey reports from causal estimates.
- One in four jobs at risk of being transformed by GenAI, new ILO–NASK global index shows
Supports the ILO's global exposure framing and its distinction between transformation and replacement.
Apply this to your own work
See the whole job market at once.
Explore which occupations AI may reshape, then turn the signal into a practical response.
Explore the job map