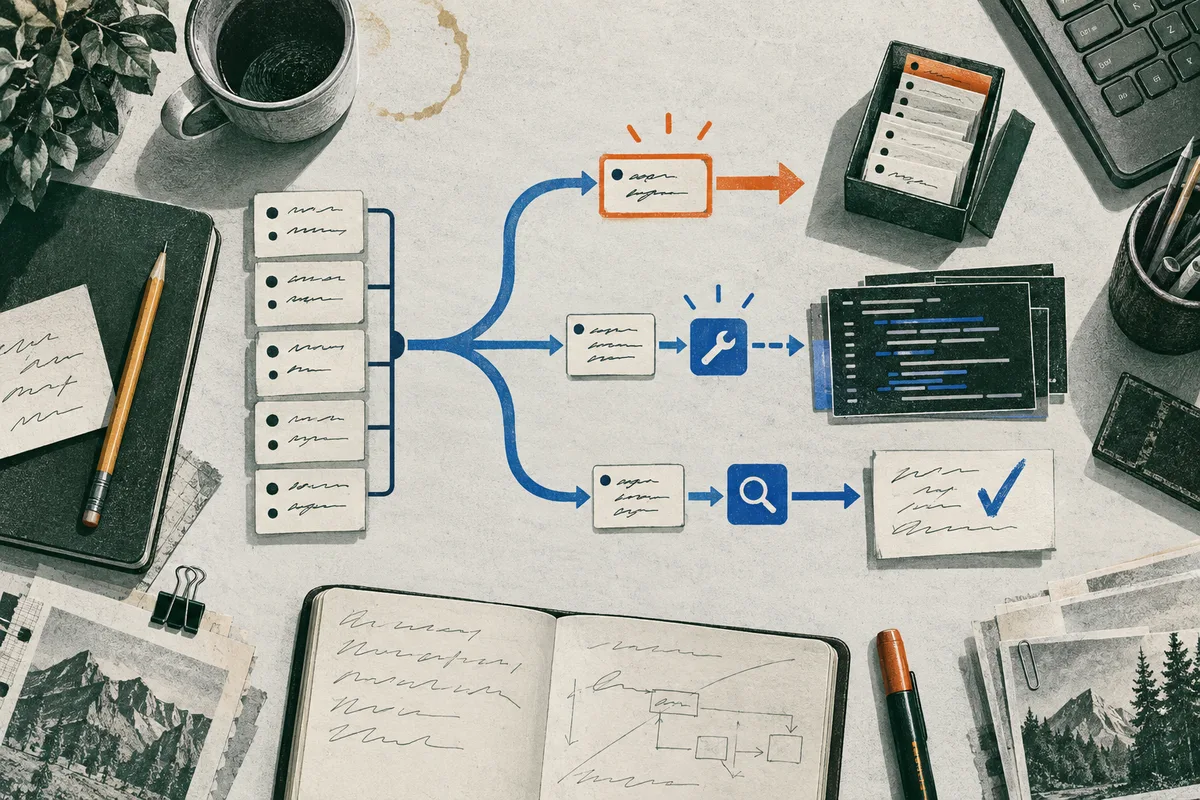
Randomized field experiments find different effects because they study different developers, tasks, tools, and definitions of completed work. A bounded coding exercise can show faster completion, a workplace trial can count more tasks, and a repository study can find slower review-ready work. These results are conditional on their settings; they do not establish a universal productivity rate or predict software employment.
What exactly is being compared when a study says ‘productivity’?
There is no single common outcome behind the headlines. Some experiments time a task, count tasks or code, or time issues that meet a human review threshold. Those measures can move differently while each study remains valid for its question. Before comparing percentages, ask who received access, what work entered the trial, whether developers used the tool, and what counted as finished. Each result is conditional on its sample, task, tool, and endpoint, not a universal rate of developer productivity.
In a randomized experiment, researchers allocate participants or tasks to conditions, such as access to an assistant or no access. That can help estimate the effect of the assigned condition within the study. It does not make participants representative of every developer, or turn one outcome into another. Access also differs from adoption: someone offered a tool may use it often, occasionally, or not at all. The Microsoft Research record describes three company trials where a random subset received code-completion assistance. Across 4,867 developers, the pooled result was 26.08% more completed tasks, while individual experiments were noisy. This concerns task counts, not minutes saved per accepted change or delivery speed across software teams.
A timed task answers a different question. In The Impact of AI on Developer Productivity: Evidence from GitHub Copilot, recruited developers were asked to implement a JavaScript HTTP server as quickly as possible. Its abstract reports that the group given Copilot access completed the task 55.8% faster than the control group. This is a time comparison for a bounded assignment. It does not measure weekly task volume or time required to maintain a mature repository and satisfy review. The number may be accurate for that endpoint; its size alone does not make it portable to another task.
Output measures have their own boundary. A count of completed tasks records units classified as complete, while lines of code record volume; neither says how much elapsed work each accepted change required. Review-ready completion adds another threshold. METR’s Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity timed real issues in familiar repositories and defined success around work expected to pass human review, including style, testing, and documentation. That finish line includes requirements a short timer or task count may not capture. A quick draft can still need correction to meet the acceptance rule.
The practical comparison is assignment and actual use, sampled developers and tasks, tool and date, completion rule, and measured outcome. Minutes saved, completed-task counts, code volume, and review-ready completion each have a different numerator, denominator, and finish line. Their results are not competing estimates of one universal speed change. When a headline seems relevant to a role, check whether its task and definition of done resemble the work at hand; that is the boundary within which it can guide a decision.
Sources: The Impact of AI on Developer Productivity: Evidence from GitHub Copilot; The Effects of Generative AI on High-Skilled Work: Evidence from Three Field Experiments with Software Developers; Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity
Why can a bounded coding task show a large time gain?
A bounded coding task can show a substantial time gain because it gives the participant a defined deliverable and a visible stopping point. That makes elapsed completion time easier to interpret than a broad question such as whether developers are more productive across a working week. In the controlled experiment described in The Impact of AI on Developer Productivity: Evidence from GitHub Copilot, recruited software developers were asked to implement an HTTP server in JavaScript as quickly as possible. The group given access to Copilot completed that task 55.8% faster than the control group, according to the study’s accessible abstract. This is a result for that assignment and measure; it is not a reported average gain for all software work.
The narrow task is both a strength and a boundary. Because the assignment names an implementation goal and asks participants to work quickly, researchers can compare time to a common endpoint. With a clear specification and checkable result, code suggestions may replace some typing, searching, or recalling routine implementation details. That is a plausible explanation, not a mechanism separately established by the abstract. A controlled comparison can support a causal interpretation within its setup more strongly than a before-and-after anecdote, but its estimate still belongs to the people, task, tool access, and completion rule studied.
The result does not tell us how much time a developer saves in an ordinary week. The abstract describes one JavaScript HTTP-server task, not a mix of debugging, design discussions, unfamiliar code, coordination, production incidents, and maintenance. Its reported completion time does not establish whether the change would pass team review, meet security and reliability requirements, or create less work later. Those costs may be immaterial for a bounded exercise or central in production; the abstract does not measure them. It also does not establish how recruited participants compare with every developer, or whether the result persists across repeated use and changing tasks.
Tool access is not routine adoption, and faster completion is not proof of autonomous delivery. The treatment group had access to the AI pair programmer; this should not be recast as evidence that everyone used suggestions alike, that organizations broadly adopted the tool, or that the assistant delivered work without developer judgment. A tool may accelerate one defined implementation while a worker still needs to frame the task, inspect the answer, run checks, and take responsibility. Those steps belong to the larger workflow, even when the timed endpoint does not include them.
Read the 55.8% figure as a reference point for a bounded implementation under the study’s conditions, not as a forecast for a mixed week or a universal productivity rate. It helps explain why a controlled exercise and a workplace study might report different effects: they can count different work and stop at different points. To decide whether assistance belongs in a recurring task, compare similar assignments against the same acceptance criteria and include review and rework in the clock. The experiment makes a large gain plausible in its setting; it does not settle the value of assistance across software development.
Sources: The Impact of AI on Developer Productivity: Evidence from GitHub Copilot
Why can a workplace trial show more completed tasks without proving faster delivery?
Workplace trials can show more recorded work without showing that an accepted change reaches users faster. Two studies illustrate the difference. In randomized company trials at Microsoft, Accenture, and an anonymous Fortune 100 company, 4,867 developers were included across three experiments. A random subset received access to a coding assistant that suggested completions. The combined analysis reported 26.08% more completed tasks (standard error 10.3%); the individual experiments were noisy, according to “The Effects of Generative AI on High-Skilled Work: Evidence from Three Field Experiments with Software Developers.” This is a result about task counts under access assignment, not minutes saved per accepted change. Assignment to access also does not mean every developer used the assistant in the same way.
The Ant Group CodeFuse field experiment makes the distinction sharper because its reported output was lines of code. The BIS record, “Generative AI and labour productivity: a field experiment on coding,” says programmers with access to CodeFuse produced 55% more lines; about one third of the increase was directly attributable to generated code. Gains were statistically significant primarily among junior staff, with less pronounced effects among senior staff. The record attributes that pattern to lower engagement among senior programmers and says suggestion acceptance did not vary with experience. This is a reported subgroup pattern, not proof that experience itself determines who benefits. Code volume and task counts answer different questions, even though both are described as productivity measures.
Neither measure alone tells a team how much time passed before a change met its normal quality bar. A count can rise while average time per task stays the same, or reflect a different task mix, more small tasks, or extra work entering the queue. These are possibilities an aggregate count can conceal, not explanations established by these trials. More lines do not establish that added code was needed, correct, reviewed, or released. A task count may capture useful throughput without recording every minute spent on review. The Microsoft record describes each experiment as noisy and reports a pooled estimate, so the combined number is not a uniform result at every workplace.
The workplace setting matters: these experiments took place in companies’ ordinary work, with their own tools, task definitions, participants, and measurement periods. That makes them relevant to those settings, but does not make the measures interchangeable or automatically transferable. For a delivery decision, teams need comparable tasks and acceptance criteria, plus elapsed time through review, accepted quality, rework, and review effort where available. Without those, a higher code or task count is evidence of more measured output under the study’s rules, not a delivery-speed promise for a particular workflow.
Sources: The Effects of Generative AI on High-Skilled Work: Evidence from Three Field Experiments with Software Developers; Generative AI and labour productivity: a field experiment on coding
Why do context, task selection, and the finish line change the measured effect?
A complex enterprise task and an issue inside a mature repository ask different things of a developer, even when both involve writing code. They therefore estimate different workflow effects. The randomized trial reported in *How much does AI impact development speed? An enterprise-based randomized controlled trial* involved 96 full-time Google software engineers and three AI features. It measured time spent on one complex, enterprise-grade task. The authors report that AI significantly shortened task time; their adjusted best estimate was about 21%, but the confidence interval was large. They also caution that the result from internal Google tools in summer 2024 may not carry across tools or over time. This is evidence for that assignment and tool setting, not a standing estimate of how much faster a developer works in a normal week.
METR asked a more repository-specific question. In *Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity*, 16 experienced contributors worked on 246 issues drawn from large repositories they had contributed to for multiple years. Each issue was randomly assigned to allow or disallow AI; allowed tools were primarily Cursor Pro with Claude 3.5 or 3.7 Sonnet, which METR described as frontier models at the time. Issues averaged about two hours. Completion meant that the contributor considered the code likely to pass human review, including style, testing, and documentation requirements. METR reports that contributors took 19% longer when AI was allowed. The sample is small and specialized, and the report explicitly says it does not establish how most developers or repositories would fare.
Those results do not form a head-to-head contest. The Google trial timed work on one complex enterprise task with three internal features; METR timed real issues in familiar open-source codebases, with a review-oriented finish line and different tools. Random assignment helps estimate the effect of the assigned condition within each study, but it does not make their participants, tasks, AI systems, or endpoints interchangeable. A reported reduction in time on one task and an increase in issue completion time can both be accurate descriptions of their respective settings.
The finish line matters because generating a plausible first draft is not necessarily the same as completing a change. In a maintained repository, a developer may need to understand surrounding behavior and conventions, fit a change to implicit requirements, run or revise tests, correct errors, and prepare documentation before the work is acceptable. AI assistance could shorten drafting while adding time to context gathering, iteration, correction, or verification. That is a plausible interpretation of why net time may differ across task bundles; neither study isolates those steps as the measured cause of the difference. METR’s stated acceptance criterion makes review-related work part of the timed outcome, while Google’s abstract describes time on its enterprise task and does not provide the same repository-issue acceptance comparison.
So match the measure to the work. For a bounded prototype with a clear stopping point, task completion time may answer the useful question. For maintenance in a particular codebase, the more relevant benchmark is a change that meets that codebase’s review expectations, including its tests and documentation. Neither result should be used as a substitute for the other. The comparison says that task context and the definition of completion can change the measured effect; it does not tell every developer which tool to use or imply that software jobs will disappear.
Sources: How much does AI impact development speed? An enterprise-based randomized controlled trial; Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity
Why did experienced contributors take longer on familiar repository work?
METR’s result is best read as a finding about one kind of maintenance work: experienced contributors changing repositories they already knew, with early-2025 tools and a human review-oriented finish line. “Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity” reports that participants took 19% longer when allowed to use AI. This matters for that setting; it does not establish that experienced developers generally slow down or that assistance has one stable effect across software work.
Repository familiarity removes some orientation costs, but an issue still has to fit existing behavior and conventions. A bug fix, feature, or refactor may need tests, documentation, and style work before a reviewer accepts it. METR recruited 16 developers who had contributed for multiple years to large open-source repositories. They supplied 246 real issues, randomly assigned to allow or disallow AI; issues averaged about two hours. In the allowed condition, participants could choose tools, primarily Cursor Pro with Claude 3.5 or 3.7 Sonnet, described by METR as frontier models at the time. Completion meant a human user was satisfied the code would pass review, including style, testing, and documentation requirements. Participants recorded screens and self-reported implementation time. Thus, the 19% finding concerns these issue tasks under these conditions, not a count of shipped features or an entire workweek.
Assistance might shorten drafting yet add time for checking changes against local conventions, correcting mistakes, or confirming tests and documentation. METR discusses implicit requirements and high quality standards as settings where AI capability may be lower. But the experiment does not isolate any one mechanism as the cause of the slowdown. These are plausible explanations to investigate, not measured causes; the result also does not show that repository familiarity itself produced the effect.
The comparison with other trials turns on the finish line. A one-shot coding exercise can stop when a specified task is complete; company trials can count tasks after developers are offered an assistant. METR timed real repository issues against a review-oriented criterion. Different task selection, participants, tools, and outcomes can yield different estimates without invalidating one another. METR explicitly cautions that its developers and repositories do not represent most software work, and that the study does not show AI fails to speed up many developers or people in other settings.
Perceived benefit can coexist with slower measured completion. METR says participants expected speedups and continued to believe they had been sped up after the tasks. The report notes possible reasons beyond immediate speed, including a more pleasant experience or learning for future use. Those outcomes matter, but they are distinct: preference does not erase elapsed time, and elapsed time does not capture every reason to choose a tool.
For maintainers, use the result as a reason to measure recurring repository tasks locally against the team’s review standard. Track acceptance, production and correction time, and testing or documentation work. It is not a reason to abandon tools or assume they always slow experts.
Sources: Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity
What does the later METR update change—and what remains uncertain?
The 2026 update from METR changes how its later result should be read, but does not provide a dependable replacement for the earlier estimate. The researchers say wider use of agentic coding tools made it harder to recruit developers willing to work without AI and obtain comparable tasks. Missing participants and tasks may be especially likely to benefit from assistance, so the observed estimate could understate uplift. METR says selection and measurement problems prevent the later data from showing the increase’s size. A newer trial can be less conclusive than an older one.
METR began the follow-up in August 2025 with ten developers from its earlier study and 47 newly recruited contributors. Developers submitted intended tasks, then each was randomized to an AI-allowed or AI-disallowed condition. Participants recorded completion time. Randomization applied after people joined and submitted tasks. It could balance conditions among entered tasks; it could not include developers who declined or tasks withheld before randomization. Random assignment within a selected sample does not make it representative of all developers or work.
METR reports that recruitment and retention became harder as developers said they did not want to do half their work without AI. In surveys, 30% to 50% said they withheld some tasks because they did not want to attempt them without AI. The researchers infer that the study missed developers and tasks with high expected uplift, likely biasing results downward. They say selection affected a minority of developers and tasks. This is the team’s interpretation, not a measured correction.
Other differences weaken a simple time comparison. METR says pay fell from $150 per hour in the earlier study to $50, possibly affecting participation. Some developers reported choosing different tasks with agentic AI, so time on submitted work might not represent the value of work otherwise chosen. Others reported differences in final quality, documentation, or tests. Some were less likely to finish tasks assigned to the no-AI condition; one participant finished none. These observations identify design concerns, but do not establish one cause.
Time was harder to attribute. Participants using multiple agents sometimes worked on another task while an agent ran, making time spent on the original task difficult to report. Elapsed time, active effort, and concurrent output do not line up neatly. METR says these problems make its central estimate a poor proxy for real productivity among these developers.
The update gives raw subgroup estimates: returning developers showed an estimated 18% speedup, with an interval from a 38% speedup to a 9% slowdown; newly recruited developers showed a 4% speedup, with an interval from a 15% speedup to a 9% slowdown. Both intervals include outcomes on either side of no effect. METR says participant conversations make a larger early-2026 speedup plausible, but selection leaves weak evidence about its size. It cautions that self-reported gains can be unreliable. These estimates do not establish a current average effect.
The methodological lesson is that adoption can change both the work measured and who remains measurable. The update makes the earlier slowdown less suitable as a stand-alone summary of current AI-assisted development, while leaving the later magnitude unresolved. Read estimates with recruitment, task-entry, pay, completion, and timing rules attached. A later date alone does not make weaker evidence more decisive, and neither study settles the average effect across developers or workflows.
Sources: We are Changing our Developer Productivity Experiment Design
How should a developer test whether assistance helps their own work?
Choose a recurring task that matters, set the acceptance rule first, and compare several similar examples with and without assistance. Track the full cycle: elapsed time, acceptance, corrections, and review effort where visible. Neither generated code nor perceived speed alone shows whether work was completed better or sooner. Name a narrow task family, such as writing tests for a familiar component or implementing a small endpoint. “Programming” is too broad: feature work, unfamiliar bugs, and test writing can involve different context and risk. Decide what “complete” means before tracking results, perhaps passing tests, reviewer acceptance, or resolving a documented issue. Keep that rule stable so a quick draft is not counted as finished against a looser bar. Record the assistant, version, and allowed workflow. Note separately whether the tool was available and actually used. In “The Effects of Generative AI on High-Skilled Work,” randomized developers received access to a code-completion assistant, and the outcome was completed tasks. Assignment to access does not mean the tool was used on every task. Follow workplace rules for confidential code, security, and approved tools; do not bypass them for a comparison. For each example, capture active and elapsed time, including waiting or review delays. Record completion, acceptance, corrections, and reviewer effort if available. If the tool creates a draft quickly but checking assumptions or repairing tests takes longer, count both. If work reaches the same acceptance bar sooner with similar correction and review, that is stronger local evidence of a gain than code volume alone. “The Impact of AI on Developer Productivity: Evidence from GitHub Copilot” timed a bounded JavaScript HTTP-server task; “Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity” used real repository issues and a review-oriented finish line. Their measures differ, which is why your own finish line must be explicit. Neither study supplies a ready-made workplace protocol. Several examples reveal a pattern, not a precise causal estimate. Tasks may differ in hidden difficulty; tool familiarity can improve; interruptions, concurrent agents, or review queues can distort time. Avoid selecting only promising cases or only failures. If alternating conditions is safe and practical, use the same task-selection rule for both. Do not force a no-tool condition that violates policy, creates unacceptable risk, or disrupts delivery. If conditions cannot be compared fairly, treat the result as a signal, not a verdict. Interpret the result at the level measured. Faster drafts with unchanged accepted completion may mean drafting improved while end-to-end work did not. Faster accepted tasks with similar rework suggest a gain in that task family. Slower completion may mean verification offsets faster generation, though a few cases cannot establish why. METR’s “We are Changing our Developer Productivity Experiment Design” describes how participant selection, task submission, and time measurement can complicate a later randomized estimate. Record what entered your comparison and how time was counted. Keep, narrow, or pause assistance for this task family based on complete accepted work and your constraints. Recheck when the task, tool, or review process changes materially. This practical check can guide a bounded workflow decision, but cannot establish a universal productivity effect.
Sources: The Impact of AI on Developer Productivity: Evidence from GitHub Copilot; The Effects of Generative AI on High-Skilled Work: Evidence from Three Field Experiments with Software Developers; Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity; We are Changing our Developer Productivity Experiment Design
What verdict is justified, and what should a developer do with it?
Randomized field experiments support a conditional verdict: AI assistance can change performance, but the direction and size depend on the task, tool, participants, workflow, and outcome measured. They do not establish one speedup or slowdown for skilled developers as a group. METR’s “Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity” studied 16 experienced contributors completing 246 issues in familiar repositories; it reported 19% longer completion with AI allowed and cautioned against generalizing to most software work. Its 2026 “We are Changing our Developer Productivity Experiment Design” describes recruitment and task-selection effects, lower pay, and difficulty measuring time when developers used concurrent agents. METR says these problems make the later estimate a poor proxy for real productivity, while judging selection effects likely to bias estimated speedup downward. That is a warning about interpretation, not a corrected universal result. A stronger conclusion would require comparable trials across task families and tool generations that count accepted quality, rework, and review alongside time. These studies do not establish market adoption, labor demand, layoffs, or anyone’s job-loss odds. For a practical next step, choose one recurring task, define acceptance, and record baseline elapsed time, corrections, and review. Compare similar work with assistance under the same criteria. This local check can guide one workflow decision; it cannot settle a career-wide question.
Sources: Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity; We are Changing our Developer Productivity Experiment Design
Questions readers ask
Do randomized AI coding studies show that developers are generally faster?
No. They estimate effects for particular participants, tasks, tools, and outcomes. Faster completion on one bounded task, more counted tasks at work, and slower review-ready repository changes are different findings, not a universal rate.
Sources and notes
- The Impact of AI on Developer Productivity: Evidence from GitHub Copilot
The accessible abstract reports a bounded JavaScript HTTP-server task and 55.8% faster completion for developers given Copilot access.
- The Effects of Generative AI on High-Skilled Work: Evidence from Three Field Experiments with Software Developers
The research record reports three randomized company trials, 4,867 developers, and a pooled 26.08% increase in completed tasks, with noisy individual experiments.
- Generative AI and labour productivity: a field experiment on coding
The BIS record supports the CodeFuse field-study comparison of code volume as an output measure distinct from elapsed time or review-ready completion.
- How much does AI impact development speed? An enterprise-based randomized controlled trial
The accessible abstract describes 96 Google engineers, one complex enterprise task, and an adjusted best estimate of about 21% shorter task time with substantial uncertainty.
- Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity
METR reports 16 experienced contributors working on 246 issues in familiar repositories and 19% longer completion time with AI allowed under a review-oriented criterion.
- We are Changing our Developer Productivity Experiment Design
METR describes participant and task-selection effects and time-measurement problems, and says the later estimate is a poor proxy for real productivity.
Apply this to your own work
See the whole job market at once.
Explore which occupations AI may reshape, then turn the signal into a practical response.
Explore the job map